Blog

  • Real Estate App Development: A Complete 2026 Guide

    Real Estate App Development: A Complete 2026 Guide

    Real estate app development is how brokerages, property managers, and PropTech founders turn a phone into the place a deal actually happens, from the first search to the signed lease. Buyers now start on a screen, expect instant pricing and a virtual tour, and lose patience with anything slower. This guide walks through what it costs, which features matter, how MLS and IDX data fits in, how long a build takes, and the decisions that separate an app that ships from one that stalls.

    We build mobile products for a living, so the advice here is what we would tell a founder or broker sitting across the table, including the parts where the honest answer is “you do not need that yet.”

    Why real estate app development is worth it in 2026

    The market has moved onto the phone and it is not moving back. The global PropTech market reached about 54.66 billion dollars in 2026 and is on track to pass 185 billion by 2034, and in JLL’s 2025 technology survey, 88 percent of real estate investors had already started piloting AI, on average across five use cases at once.

    For Millennials and Gen Z, the property search begins on a phone. They expect instant pricing, virtual tours, digital mortgage tools, and smart-home data as standard, not as extras. A brokerage or platform without a fast, modern app is quietly handing those buyers to one that has it.

    That does not mean everyone needs a custom app. It means the ones who compete on speed, listings, and experience increasingly do, and the gap between a good app and a slow website keeps widening.

    What a real estate app actually does

    “Real estate app” covers several very different products, and knowing which one you are building is the first real decision. The three most common shapes:

    A listing and search marketplace, like a smaller Zillow or Realtor.com, where buyers and renters browse properties, save searches, and contact agents. A brokerage or agent app, branded to one firm, that shows its listings, captures leads, and helps agents work in the field. A property management app, where owners and managers track units, tenants, leases, rent payments, and maintenance requests.

    Each serves a different user and needs a different core. A marketplace lives or dies on listing data and search. A management app lives on payments, documents, and tenant communication. Building the wrong one first is the most expensive mistake in this space, so we scope the product around who uses it and what job they are doing before writing any code.

    Must-have features for real estate app development

    Features drive both value and cost, so the goal is the smallest set that solves the real job, not the longest list. The core features most real estate apps genuinely need:

    Property listings and search. Rich listings with photos, video, price, and location, plus fast filtering by price, beds, type, and neighborhood. This is the heart of a buyer-facing app and where most of the engineering attention goes.

    Saved searches and alerts. Buyers set criteria once and get an email or push notification the moment a matching property appears. In a fast market this single feature drives more engagement than almost anything else.

    Maps and location. Map-based browsing, commute and neighborhood context, and pins that make a list of addresses feel like a place. Mapping APIs handle most of the heavy lifting here.

    Agent contact and lead capture. A clean path from “I like this” to “talk to a person,” with the lead landing in a CRM rather than a lost inbox. For brokerages, this is the feature that pays for the app.

    Virtual tours and media. 3D tours, interactive floor plans, and video walkthroughs are now standard expectations, not premium add-ons. They reduce wasted physical visits and keep serious buyers engaged.

    A dashboard. An agent, seller, or property-manager view to manage listings, leads, or units in one place, tuned to who is actually logging in every day.

    Payments (for management apps). Rent collection, deposits, and fees through a secure payment gateway, with clear records for both tenant and owner.

    Advanced features like AI valuation, in-app mortgage tools, and e-signature closing are real differentiators, and we cover them below. The discipline is shipping the core first and adding those once the app has real users.

    MLS and IDX integration in real estate app development

    If your app shows live listings in the United States, MLS and IDX integration is usually the single biggest technical and cost decision, so it deserves its own section.

    The MLS (Multiple Listing Service) is the database of listings brokers share in a region. IDX (Internet Data Exchange) is the rule set and feed that lets you display those listings on your own site or app. Pulling live listing data means licensing the feed, mapping its fields to your data model, and building sync logic that keeps everything current as listings change, sell, or expire.

    That work is not trivial. MLS/IDX integration commonly adds roughly 15,000 to 35,000 dollars to a project, and a single full MLS integration can run 20,000 to 60,000 dollars once licensing, data mapping, and sync are done properly. There are hundreds of MLSs in the US, each with its own feed and rules, so covering multiple regions multiplies the effort.

    Two practical points save real money here. First, start with the MLS regions you actually operate in, not the whole country. Second, follow the data standards from the Real Estate Standards Organization, whose RESO Web API is the modern way MLS data is exchanged and what most current feeds use. Building to that standard from day one avoids expensive rework later.

    How much does real estate app development cost in 2026?

    Cost tracks scope far more than it tracks any agency’s rate card, so treat every headline number as a range until your features are scoped. As rough 2026 figures:
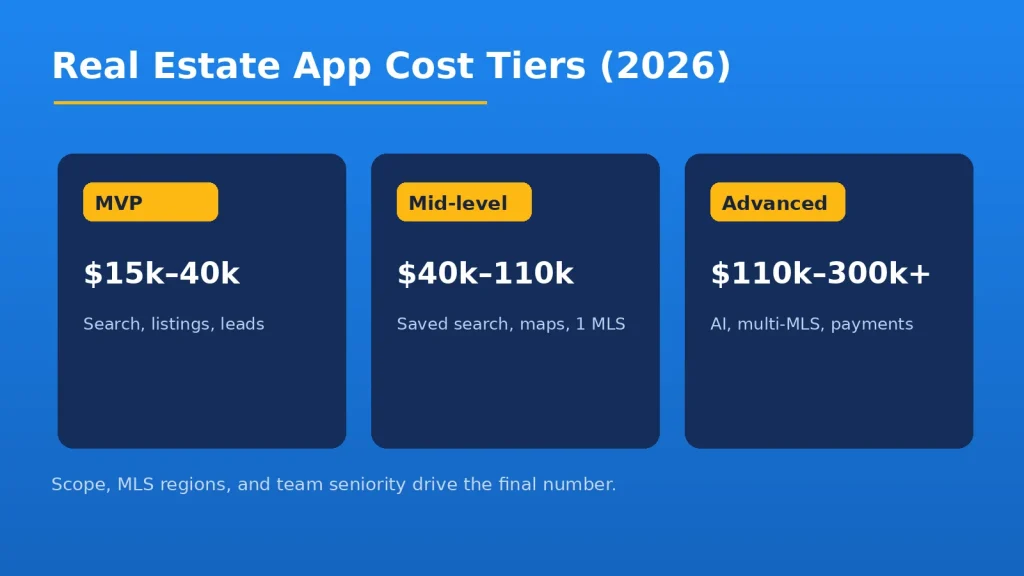
    Real estate app development cost tiers for 2026

    A basic MVP with core search, listings, and lead capture runs about 15,000 to 40,000 dollars. A mid-level app with saved searches, dashboards, maps, and one MLS feed lands around 40,000 to 110,000 dollars. An advanced platform with AI features, multi-MLS aggregation, payments, and deep integrations runs 110,000 to 300,000 dollars and up.

    For production-grade products built in the US with senior teams, real ranges are higher: an MVP often lands at 80,000 to 180,000 dollars, and a full v1 platform at 180,000 to 450,000 dollars. A white-label app you customize rather than build from scratch can start around 20,000 to 80,000 dollars, and a national multi-MLS marketplace can reach 1.5 million dollars or more.

    The biggest cost levers are the number of MLS regions, whether you build native or cross-platform, the depth of payments and compliance, and how senior the team is. For a broader view of how mobile budgets are set, see our guide to mobile app development cost.

    How long does real estate app development take?

    Timeline follows scope the same way cost does. A typical real estate app runs about 4 to 9 months from discovery to launch. A simpler build using an API-only IDX feed can ship in 1 to 3 months, while a multi-MLS aggregation platform with AI-native features can stretch to 9 to 12 months.

    The variables that move the timeline are the number of MLS integrations, payment and compliance requirements, how much custom design you want, and how quickly decisions and feedback move on your side. A good partner ships in stages, so you see a working app on a narrow slice early and expand from there, rather than waiting many months for one large release.

    We usually recommend launching a focused MVP, getting it in front of real agents or buyers, and letting their behavior guide the next features. It is cheaper to learn from a live app than to guess in a requirements document.

    The real estate app development process, step by step

    A well-run real estate app development project moves through seven clear stages, and knowing them helps you spot a partner who skips the important early work.

    1. Discovery and scoping. We define who uses the app, which regions and MLS feeds matter, and what the first version must do. This is where most budget is saved or wasted, so it comes before any design or code.

    2. UX and design. We map the core flows, search, listing detail, lead capture, dashboard, and design screens around how agents and buyers actually behave in the field, not around a feature list.

    3. Architecture and data model. We decide native versus cross-platform, plan the listing and user data model, and design MLS/IDX sync so the app stays fast and current as data changes.

    4. Development. Senior engineers build the app in short cycles, so you see working screens early rather than waiting months for one big reveal. Integrations like maps, payments, and feeds are wired in with clear contracts.

    5. Testing. We test on real devices, real network conditions, and real MLS data, because a listing app that is slow or wrong on a phone loses trust instantly. Security testing matters here for any app holding financial or tenant data.

    6. Launch. We ship to the App Store and Google Play, handle their review requirements, and roll out to real users. A focused MVP launch beats a delayed everything-at-once release.

    7. Maintenance and iteration. The app is not done at launch. OS updates, MLS feed changes, and real user behavior all demand ongoing care, so support and a roadmap are agreed up front rather than as an afterthought.

    A team that races past discovery and testing to start coding is optimizing for its invoice, not your outcome. The early and late stages are exactly where real estate apps succeed or quietly fail.

    The 2026 trends worth building for

    A few trends have moved from “nice to have” to something buyers now expect, and they are worth designing for even in an MVP roadmap.

    AI property valuation. Automated Valuation Models give instant, data-driven price estimates from comparable sales, market trends, and neighborhood data. In 2026 these are evolving into “living valuations” that adjust as the market moves, and buyers increasingly expect an instant number rather than “contact us for pricing.”

    Immersive virtual tours. Photos alone no longer cut it. 3D tours, interactive floor plans, and AR/VR walkthroughs let buyers explore a property from the couch, which filters out weak leads and keeps serious ones engaged.

    Digital mortgage and closing. Payment gateways, mortgage calculators, e-signatures, and online notarization inside the app shorten closing times and keep the buyer in your product instead of bouncing to a bank’s site. Even a simple in-app mortgage calculator meaningfully lifts engagement.

    Smart-home and neighborhood data. Buyers, especially younger ones, want context: schools, commute, walkability, and smart-home details surfaced right on the listing.

    None of these need to be in version one, but the ones you plan to add should shape how the app is architected now, so adding them later is an upgrade rather than a rebuild.

    Native or cross-platform for a real estate app?

    Most real estate apps do not need two separate native codebases, and this choice has a real effect on budget and timeline. Cross-platform frameworks like React Native or Flutter let you ship to both iOS and Android from one codebase, which lowers cost and speeds delivery, and they handle listings, search, maps, and dashboards comfortably.

    Native iOS and Android make sense when you need maximum performance, heavy AR/VR tours, or deep device features, and can support two codebases. For most brokerages and PropTech MVPs, cross-platform is the pragmatic starting point, and you can go native later for a specific feature if the product demands it.

    The right call depends on your users, budget, and roadmap, and a good partner explains the trade-off rather than defaulting to whatever they staff. If you are weighing it up, our mobile app development team scopes this with you before anything is built.

    Common real estate app development mistakes to avoid

    The failures in this space tend to repeat, and most are avoidable with honest scoping up front.

    Building for the whole country’s MLS data on day one, when you operate in two regions, burns budget you could spend on the actual product. Cramming every feature into version one delays launch and hides which features users truly want. Ignoring data security when the app holds tenant and financial information invites a breach you pay to fix twice. Treating the app as done at launch, with no plan or budget for maintenance and OS updates, guarantees it degrades within a year.

    The pattern behind all of these is skipping the scoping conversation. A short, honest discovery that pins down who uses the app, which regions matter, and what the first version must do prevents most expensive mistakes before a line of code is written.

    How to choose a real estate app development partner

    The team you pick matters more than any single feature, so judge them the way you would judge a contractor building your house. Ask who exactly will write your code and how senior they are, because a senior pitch that turns into a junior build is the most common bait-and-switch in app development.

    Ask for shipped work in real estate or a similar data-heavy domain, ideally apps you can download and use today. Confirm you will own the source code, the IP, and the app store listings in writing, with no lock-in. Get a clear answer on MLS/IDX experience, since that is where inexperienced teams underestimate the work. And ask what maintenance and support cost after launch, because a team with no answer there is planning to disappear after the invoice clears.

    Third-party reviews on independent platforms and reference calls with past clients tell you more than any sales deck. When you are ready to staff a build, you can also hire mobile developers who already work with maps, payments, and listing data to extend your own team.

    Frequently asked questions

    How much does it really cost to build a real estate app?

    A basic MVP runs about 15,000 to 40,000 dollars, a mid-level app 40,000 to 110,000 dollars, and an advanced platform 110,000 to 300,000 dollars or more. Production-grade US builds start higher, often 80,000 to 180,000 dollars for an MVP. The biggest cost drivers are MLS integration, payments, and how senior the team is, so scope the features before trusting any single number.

    What features should my real estate app have first?

    Start with property listings and search, saved searches with alerts, map-based browsing, agent contact and lead capture, and a simple dashboard. For property management apps, add rent payments and tenant communication. AI valuation, virtual tours, and mortgage tools are strong differentiators, but ship the core first and add them once you have real users.

    Do I need MLS or IDX integration, and what does it cost?

    If your app shows live US listings, yes. MLS/IDX integration means licensing a listing feed, mapping its data, and keeping it in sync, which commonly adds 15,000 to 35,000 dollars, and a single full MLS integration can reach 20,000 to 60,000 dollars. Start with the regions you actually operate in and build to the RESO data standard to avoid rework.

    How long does it take to develop a real estate app?

    About 4 to 9 months from discovery to launch for a typical app. A simpler build on an API-only IDX feed can ship in 1 to 3 months, while a large multi-MLS platform with AI features can take 9 to 12 months. Launching a focused MVP first and expanding from there is usually faster and cheaper than one big release.

    Should I build a real estate app without being a developer?

    You do not need to be a developer, but you do need a technical partner. No-code tools can validate a simple idea, but they hit limits fast on MLS data, payments, and scale. For anything you plan to grow, a senior development team that scopes honestly and hands you full ownership is the safer path than trying to assemble it yourself.

    Native or cross-platform, which is better for a real estate app?

    Cross-platform frameworks like React Native or Flutter suit most real estate apps, cost less, and ship to iOS and Android from one codebase. Native makes sense when you need maximum performance or heavy AR/VR tours. For most brokerages and PropTech MVPs, cross-platform is the pragmatic starting point.

    Should my real estate app have AI or machine learning features?

    AI valuation, smart search, and lead scoring are genuinely useful in 2026 and increasingly expected by buyers. They are worth planning for, but they are not where you start. Ship a fast, reliable core app first, then add AI features once you have data and users, so the AI improves a working product rather than propping up an unfinished one.

    How do I make money with a real estate app?

    Common models include agent or brokerage subscriptions, per-listing or featured-listing fees, lead-generation fees paid by agents, transaction or referral fees, and premium tools for power users. Property management apps often charge a per-unit monthly fee. Pick the model that fits your users before you build, because it shapes the product.

    What security do real estate apps need?

    Any app holding tenant, buyer, or financial data needs encryption in transit and at rest, secure authentication, least-privilege access to sensitive records, and secure payment handling through a compliant gateway. For apps that touch payments or personal financial data, security and compliance should be designed into the architecture from the start, not added later.

    Should I use existing real estate software or build custom?

    Off-the-shelf software is cheaper and faster when your needs are standard, and white-label apps sit in between at roughly 20,000 to 80,000 dollars. Build custom when your workflow, branding, or data needs are specific enough that existing tools force awkward compromises. The honest answer is often to start with something proven and build custom only where it creates real advantage.

    Build a real estate app that ships

    Real estate app development rewards focus: the right product shape, a lean first version, the MLS regions you actually serve, and a partner who tells you what to cut. Get those right and the app becomes the place your deals happen, rather than another project that stalls in scope.

    Planning a real estate app? Talk to Mobilions. A senior engineer will scope it with you, give you an honest cost and timeline, and recommend the smallest version that proves the idea. Book a discovery call or explore our mobile app development services.
  • Mobile Health App Development: A Complete 2026 Guide

    Mobile Health App Development: A Complete 2026 Guide

    Mobile health app development is where good software meets real medical stakes. When your app tracks a heartbeat, reminds someone to take insulin, or carries a diagnosis between a patient and a doctor, a bug is not an inconvenience, it is a safety and compliance event. That single fact separates it from ordinary app work.

    This guide covers what mobile health app development actually involves in 2026: the app types worth building, the features that matter, the compliance you cannot skip, real costs and timelines, and how to choose a partner. It is written from the perspective of engineers who build and support healthcare software in production, not from a brochure. If you want the broader enterprise view, see our guide to healthcare mobile app development; this one focuses on patient-facing and connected mHealth apps.

    What is mobile health app development?

    Mobile health app development, often called mHealth, is the process of designing, building, securing, and maintaining mobile apps that deliver health services to patients or clinicians: telemedicine, remote monitoring, medication management, fitness and wellness, and access to medical records.

    The users are patients, caregivers, doctors, or all three. The data is some of the most sensitive there is. And in many cases the app influences a health decision, which can pull it into medical-device regulation. Those three realities shape every choice in a build.

    The market reflects the demand. The global mHealth apps market is projected to reach about $45 billion in 2026 and more than double by the mid-2030s. But the winners are not the apps with the most screens; they are the ones users trust with their health day after day, which is earned in security, accuracy, and experience.

    What types of mobile health apps can you build?

    Most mHealth projects fall into a few proven categories, and knowing which one you are building sets the scope.

    Telemedicine apps connect patients and clinicians for video visits, chat, and e-prescriptions. Remote patient monitoring (RPM) apps collect vitals from the patient, often through wearables, and surface them to a care team. Together with EHR/EMR access apps, these are the three highest-demand categories in 2026.

    Beyond those, there are medication and chronic-care management apps, mental health and wellness apps, fitness and lifestyle apps, and clinical tools for providers. The lighter the clinical role, the lighter the compliance; a wellness step-counter is not regulated like an app that recommends an insulin dose. Naming your category early tells you honestly how heavy the build will be.

    What features should a mobile health app include?

    Features fall into three layers: the basics patients expect, the ones that drive retention, and the clinical and security features that make the rest safe to ship.

    The basics are secure sign-in, a clear health dashboard, appointment booking, and reliable notifications. If these are slow or confusing, adoption stalls, and an unused health app helps no one.

    The retention drivers are what turn an install into a habit: video consultations, secure messaging with a clinician, medication and appointment reminders, and integration with wearables and fitness trackers so data flows in automatically. In 2026, AI-assisted features like symptom triage and personalized insights are increasingly expected too, though they must be handled carefully when they touch clinical decisions.

    The third layer is clinical and security capability: EHR access, e-prescriptions, consent management, audit logging, and encryption everywhere. These are not glamorous, but they are the difference between a demo and a system a hospital or patient will actually trust.

    Compliance: the non-negotiable core of mHealth

    In healthcare, compliance is the product, not a phase you bolt on later. This is the single most important thing to understand before you budget.

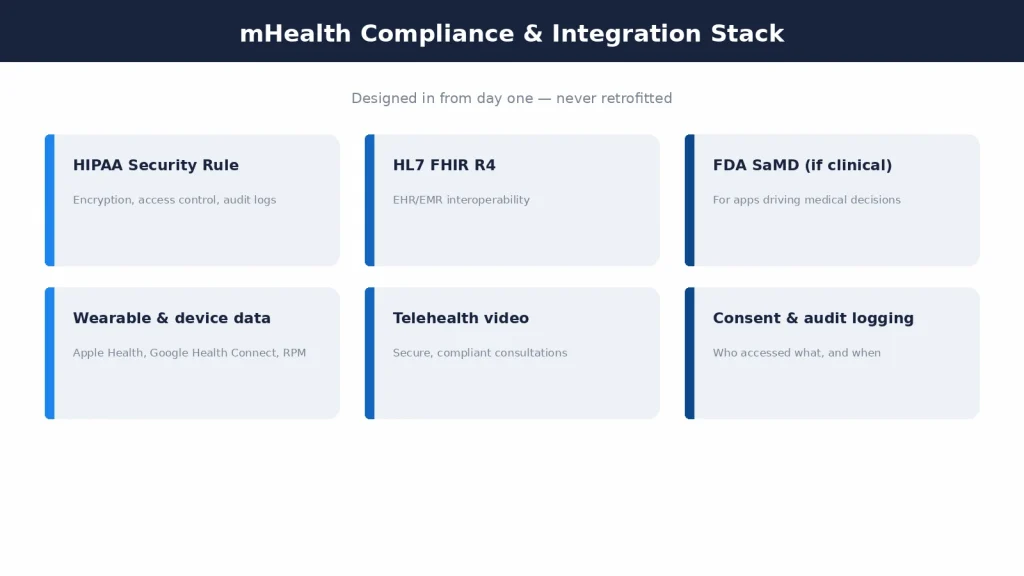
    mHealth compliance and integration stack (HIPAA, FHIR, wearables) by Mobilions

    A serious mHealth app usually has to satisfy three layers. First, HIPAA in the US governs how protected health information is stored, transmitted, and accessed; building to the U.S. Department of Health and Human Services HIPAA Security Rule is mandatory for any app touching PHI, and it typically adds 20 to 30 percent to a project. Second, EHR interoperability runs on HL7 FHIR (the R4 standard), which is how your app exchanges records with hospital systems. Third, if the app drives a clinical decision, it may be classified as Software as a Medical Device and fall under FDA SaMD rules.

    Compliance cannot be retrofitted. Encryption, access control, consent, and audit trails have to be designed into the architecture from the first commit; adding them to a finished app costs far more and often forces a redesign. A vendor who quotes mobile health app development without a detailed compliance plan has not scoped the hard part.

    How much does mobile health app development cost in 2026?

    Cost scales with clinical complexity, compliance, and integrations far more than with screen count. With that framing, 2026 numbers fall into clear bands.

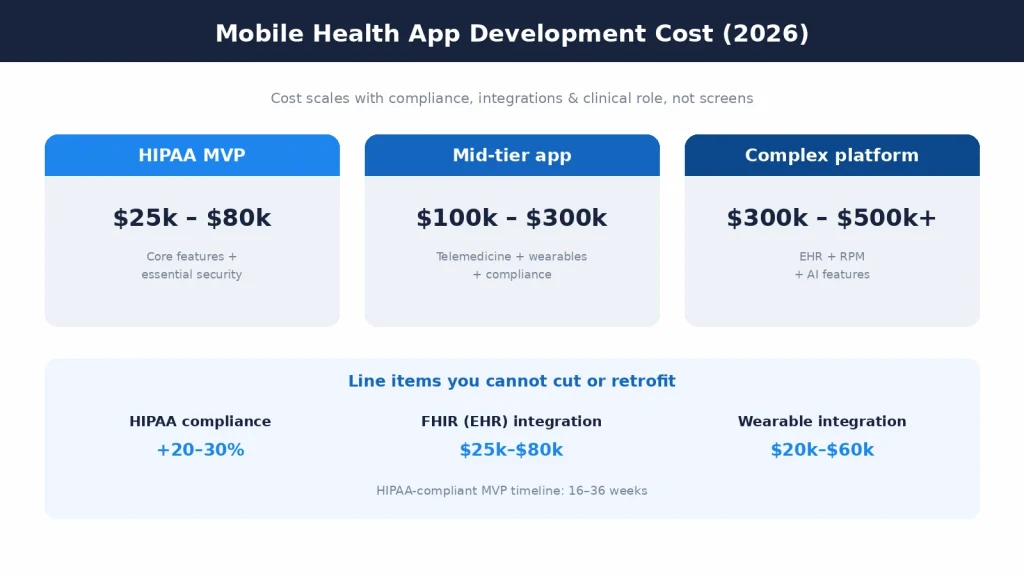
    Mobile health app development cost bands for 2026 by Mobilions

    A HIPAA-compliant MVP, with core features and essential security, runs roughly $25,000 to $80,000. A mid-tier app, with telemedicine, wearable integration, and full compliance, runs about $100,000 to $300,000. A complex platform, with EHR integration, RPM, and advanced or AI features, runs $300,000 and can pass $500,000 for the largest programs.

    Inside those totals, the big line items are specific. HIPAA compliance adds 20 to 30 percent. A FHIR R4 integration adds roughly $25,000 to $80,000 and 90 to 120 days. Wearable and medical-device integration to track vitals adds $20,000 to $60,000. None of these are safe places to cut, because they are exactly what makes the app usable, connected, and legal.

    The most useful thing you can do for your budget is scope compliance and integrations early. That is where mobile health app development costs are made or blown, and an honest partner will tell you which band your requirements fall into before you commit.

    How long does it take to build a mobile health app?

    Timelines track complexity, not ambition. A HIPAA-compliant mHealth MVP typically takes 16 to 36 weeks. A full platform with EHR integration and compliance certification runs longer, often into 12 to 18 months.

    The parts that extend timelines are rarely the screens. They are the FHIR integration (90 to 120 days on its own), the security hardening, the compliance work, and the testing a health app demands before it can touch real patient data. A realistic schedule builds these in rather than treating them as a final sprint.

    A good partner defines milestones in discovery so you have an honest timeline before building starts, and ships in visible iterations rather than disappearing into a long black box.

    Native or cross-platform for a health app?

    This is a common question, and the honest answer is that both work when done right.

    Cross-platform frameworks like React Native and Flutter serve most mHealth apps well, letting you build for iOS and Android from one codebase and roughly halving build and maintenance cost. They are entirely capable of secure, HIPAA-compliant healthcare apps; the reliability comes from the engineering, not the framework.

    Native development, with Swift for iOS and Kotlin for Android, is worth it when you need the deepest device and sensor integration, the tightest performance, or the most direct access to platform health frameworks like Apple HealthKit and Google Health Connect. Many RPM apps lean native for exactly that reason.

    The right call depends on your features and your data sources. A good team recommends based on your requirements, not on what it prefers to build.

    Integrations that make a health app useful

    An mHealth app is only as valuable as what it connects to, and each integration carries its own security and compliance weight.

    The EHR/EMR integration through FHIR is the foundation for any clinical app; it is how records flow between your app and hospital systems. Wearable and device integration (Apple Health, Google Health Connect, and specific medical devices) is what powers remote monitoring and automatic vitals capture. Telehealth needs a secure, compliant video layer. And identity, payments, and pharmacy or lab integrations round out a full patient experience.

    Because each of these touches sensitive data, the integration layer, not the UI, is usually where most of the real engineering time goes. This is the heart of mobile health app development, and it is what a serious healthcare software team scopes first.

    Why user experience matters more in health apps

    In most apps, poor UX costs engagement. In a health app, it can cost adherence, which is the whole point. If a patient cannot find how to log a symptom, book a visit, or take the right dose, the app has failed at its job even if every feature works.

    Good mHealth UX means accessibility for older and impaired users, plain language over medical jargon, minimal steps for the actions that matter, and clarity under stress. It also means designing trust: people share health data only with apps that feel safe and legitimate. Design is not decoration here; it is part of the clinical outcome.

    The team behind a mobile health app

    A serious mobile health app development effort needs more than app developers. It needs mobile engineers for iOS and Android, backend engineers for the API and integration layer, a security specialist who owns encryption and threat modeling, a compliance lead who knows HIPAA and FHIR, a UX designer who understands clinical and accessibility needs, and QA engineers who test against real-world and adversarial scenarios.

    You rarely need all of these full-time from day one, which is why many clinics and health startups work with an experienced custom software development partner who brings the compliance and integration expertise that is hardest to hire. The point is that a health app is a multi-disciplinary build, and treating it as just “an app” is exactly how the compliance and security gaps appear.

    Mobile health app trends in 2026

    The bar for a competitive health app keeps rising, and mobile health app development in 2026 has to account for a few clear shifts.

    The biggest is AI moving into care. Symptom triage, personalized health insights, and administrative automation are increasingly expected, but they raise the compliance stakes: the moment AI influences a clinical decision, the app moves toward Software as a Medical Device territory and needs the governance to match. AI in health is powerful, but it is not a place for shortcuts.

    Remote patient monitoring is the second shift. With wearables now mainstream, patients expect their vitals to flow into an app automatically and reach their care team without a manual step. This is driving RPM from a niche feature into a baseline expectation for chronic-care and post-acute apps.

    Interoperability is the third. FHIR has become the common language of health data, and patients increasingly expect to see and move their records across providers from one app. An mHealth app that cannot exchange data cleanly feels closed and dated. Accessibility and multi-language support round out the modern baseline, because a health app that excludes users is both a business miss and, often, a compliance one. The takeaway is that these are core scope now, not later upgrades.

    Why healthcare apps fail, and how to avoid it

    Most healthcare-app trouble is predictable, and nearly all of it traces back to underestimating the hard parts.

    The first mistake is treating compliance and security as a later phase. Retrofitting HIPAA controls, encryption, and audit logging into a finished app costs far more than building them in, and it often forces a rebuild. Security scoped late is security done twice.

    The second is pricing screens instead of integrations and compliance. The visible app is the cheap part; FHIR integration, the security layer, and regulatory work are where the budget lives. A quote that ignores them will be wrong.

    The third is ignoring adoption: an app that is clinically correct but hard to use gets abandoned, and a health app nobody opens delivers no outcomes. The fourth is shipping and stopping; a health app needs ongoing maintenance to stay compliant, secure, and current as regulations and devices change.

    How to choose a mobile health app development company

    The right partner talks about your compliance, your integrations, and patient safety before it talks about screens. That is the fastest signal that they have built healthcare software before.

    Look for real HIPAA and FHIR experience, a documented security track record, healthcare projects in the portfolio, and a support model that lasts beyond launch. Ask how they handle PHI, consent, and audit logging, and whether they have shipped EHR or wearable integrations, because a team that has done this will have clear answers.

    Be cautious of quotes that price only the visible app, and of anyone promising a fully compliant health app on a consumer-app budget and timeline. Ownership matters too: you should own the code, the infrastructure, and the data pipelines, with no lock-in.

    Why some health apps cost $50k and others $500k

    The same phrase, mobile health app development, can describe a $50,000 project and a $500,000 one, and the gap confuses a lot of founders. The difference is almost never the number of screens.

    A $50,000 app is usually a focused MVP: one clear use case, a handful of features, standard authentication, and light or no clinical role. A $500,000 app carries deep EHR integration through FHIR, remote monitoring with medical-device data, telehealth video, multiple user roles, formal compliance certification, and often AI. Each of those is a serious engineering workstream, not a screen.

    Three factors drive most of the spread: compliance depth (a wellness tracker versus an FDA-regulated clinical tool), integration count (a standalone app versus one wired into hospital systems and devices), and data sensitivity (how much protected health information flows through it). Understand those three and the price stops being a mystery. It also means the honest first step is scoping, because a vendor who quotes before understanding your clinical role and integrations is guessing.

    A quick example: what an mHealth build looks like

    Consider a clinic that wants a remote patient monitoring app for chronic-care patients. It needs secure login, a patient dashboard, automatic vitals from a wearable, alerts to the care team, secure messaging, and integration with the clinic’s EHR, all under HIPAA.

    The scope decisions follow directly. Cross-platform on React Native to reach iOS and Android affordably, or native if the wearable integration demands it. A FHIR R4 integration to exchange records with the EHR. Wearable integration through Apple Health and Google Health Connect for vitals. Encryption everywhere, consent management, and audit logging from day one, with a compliance workstream running in parallel.

    Notice what drove every decision above: not the number of screens, but the systems the app had to connect to and the health data it carried. Change the EHR, the device, or the clinical role and the estimate changes with it. The screens were the fastest part to build and the least important to the outcome.

    On these requirements the project lands in the mid-to-complex band, and the FHIR integration, wearable work, security, and compliance, not the screen count, set the price and the timeline. That is mobile health app development in one concrete picture: the app is the easy part, and the trust and connectivity underneath it are the real product.

    Frequently asked questions

    What is mobile health app development?

    Mobile health app development (mHealth) is building mobile apps that deliver health services to patients or clinicians, such as telemedicine, remote monitoring, medication management, and records access, engineered to protect sensitive health data and meet regulations like HIPAA.

    How much does it cost to build a mobile health app in 2026?

    A HIPAA-compliant MVP runs about $25,000 to $80,000, a mid-tier app with telemedicine and wearables about $100,000 to $300,000, and a complex EHR-integrated platform $300,000 or more. HIPAA adds 20 to 30 percent, a FHIR integration $25,000 to $80,000, and wearable integration $20,000 to $60,000.

    Does my mobile health app need HIPAA compliance?

    If it stores, transmits, or accesses protected health information in the US, yes, HIPAA is mandatory. Apps that exchange records with hospitals also need HL7 FHIR, and apps that drive clinical decisions may fall under FDA Software as a Medical Device rules. Compliance must be built in from the start.

    How long does it take to build a mobile health app?

    A HIPAA-compliant MVP typically takes 16 to 36 weeks; a full platform with EHR integration and compliance certification runs 12 to 18 months. FHIR integration alone adds 90 to 120 days, and security and compliance testing extend timelines further.

    What features should a mobile health app have?

    Core features are secure login, a health dashboard, appointment booking, and notifications. High-value features are video consultations, secure messaging, medication reminders, and wearable integration, all wrapped in encryption, consent management, and audit logging.

    Can React Native be used for serious healthcare apps?

    Yes. React Native and Flutter are fully capable of secure, HIPAA-compliant health apps, and cross-platform roughly halves cost. Native (Swift/Kotlin) is worth it when you need the deepest device, sensor, or health-framework integration, common in remote monitoring apps.

    How do you protect patient data in a health app?

    Through end-to-end encryption in transit and at rest, strong authentication, least-privilege access control, consent management, secure local storage, and full audit logging, all aligned to the HIPAA Security Rule and designed in from the first commit rather than added later.

    How do you choose a mobile health app development company?

    Choose one that scopes compliance, integrations, and patient safety before pricing screens, has real HIPAA and FHIR experience, shows healthcare projects, supports the app beyond launch, and hands you full ownership of the code and data.

    Build a health app patients and clinicians can trust

    Mobile health app development succeeds or fails on the parts users never see: the compliance, the integrations, and the security. If you are scoping a health app and want an honest read on cost, timeline, and what production really requires, talk to Mobilions. Senior engineers who build healthcare and mobile apps scope it, build it, secure it, and support it in production, with compliance planned from day one.

  • Mobile Banking App Development: A Complete 2026 Guide

    Mobile Banking App Development: A Complete 2026 Guide

    Mobile banking app development is one of the few software projects where a single security gap can end the business, not just the product. That is what makes it different from an ordinary app: the users are trusting you with their money, and the regulators are watching how you handle it. Get it right and you have a product people open every day; get it wrong and you have a breach, a fine, and a headline.

    This guide walks through what mobile banking app development actually involves in 2026, from the features that keep users, to the security and compliance you cannot skip, to what it costs, how long it takes, and how to choose who builds it. It is written from the perspective of engineers who ship and support production financial software, not from a sales deck.

    What is mobile banking app development?

    Mobile banking app development is the process of designing, building, securing, and maintaining a mobile application that lets customers manage money: check balances, move funds, pay bills, and control cards, all connected to a core banking system in real time.

    The app is the visible part, but most of the real work is invisible: the integration with core banking, the security layer, the compliance controls, and the fraud detection that runs behind every tap. A banking app that only looks good is a demo. A banking app that stays accurate, secure, and compliant under real traffic is a product.

    That distinction shapes every decision in this guide. In consumer apps you optimize for delight; in mobile banking app development you optimize for trust, and trust is earned in the parts users never see.

    What features should a mobile banking app include?

    Features fall into three layers: the basics users expect, the ones that drive retention, and the security features that make the rest safe to ship.

    The basics are table stakes: account overview and balances, transaction history, fund transfers, bill payments, and card management. If any of these is slow or confusing, users go back to the website, and you have lost the point of the app.

    The retention drivers are what separate a banking app people tolerate from one they rely on. The highest-impact ones in 2026 are biometric login, real-time transaction alerts with instant card controls, instant peer-to-peer payments, AI-powered spending insights, and fast in-app support. These are the features that turn an account into a habit.

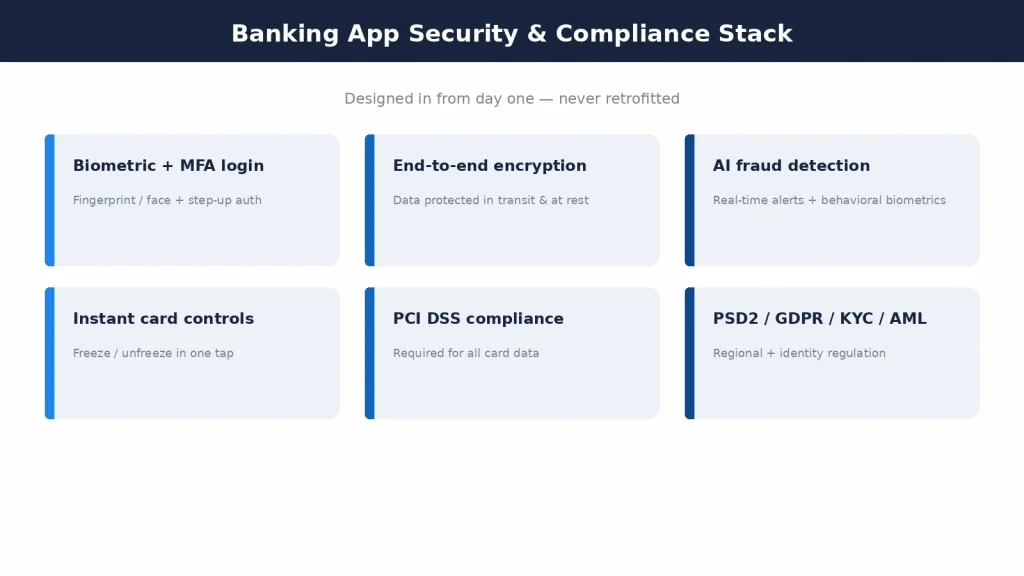
    The third layer is security, and it is not optional in a banking context. A complete stack includes biometric authentication, multi-factor authentication for high-risk actions, end-to-end encryption, AI-powered fraud detection with real-time alerts, instant card freeze and unfreeze, and behavioral biometrics for continuous session checks. We will come back to this, because it is where the budget and the risk concentrate.

    The trap is treating features as a checklist. The right feature set depends on who your customers are and what they actually do with their money, which is why good mobile banking app development starts with the customer, not the feature list.

    Security and compliance: the non-negotiables

    In banking, security and compliance are the product, not a phase you add at the end. This is the single most important thing to understand before you budget or plan.

    Mobile banking app security and compliance stack by Mobilions

    Security cannot be retrofitted. Security added at the end of development is harder to get right and far more expensive to fix. It has to be designed into the architecture from the first commit. In practice, security work alone can consume roughly a fifth of the budget before a single customer-facing feature is built, and that is money well spent rather than overhead.

    The security layer includes encryption of data in transit and at rest, secure authentication (biometric plus MFA), certificate pinning, jailbreak and root detection, secure local storage, and real-time fraud monitoring. Aligning the build to a recognized standard such as the OWASP Mobile Application Security project turns “we think it is secure” into something you can actually verify.

    Compliance is a legal gate, not a nice-to-have. A banking app has to satisfy PCI DSS for card data, plus regional rules like PSD2 in Europe, GDPR for personal data, and KYC and AML for identity and anti-fraud. This regulatory work typically adds $30,000 to $100,000 to a project and, like security, cannot be bolted on afterward. Anything that touches card data must follow the PCI Security Standards Council requirements from day one.

    Biometric authentication deserves special mention because users now expect it and it is central to both security and experience. Building it against an open standard like the FIDO Alliance specifications keeps it interoperable and future-proof rather than tied to one vendor.

    The honest summary: if a vendor quotes mobile banking app development without a detailed security and compliance plan, they have not scoped the hard part, and the number will move once reality arrives.

    How much does mobile banking app development cost in 2026?

    Cost scales with security, compliance, and integration depth far more than with the number of screens. With that framing, 2026 numbers fall into clear bands.

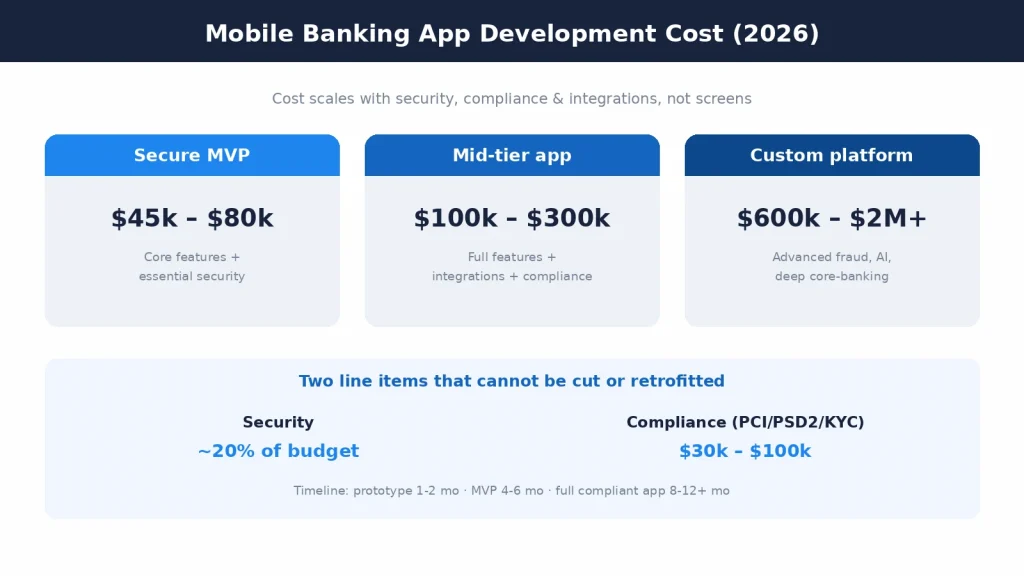
    Mobile banking app development cost bands for 2026 by Mobilions

    A basic MVP, with core banking features and essential security, starts around $45,000 to $80,000. A mid-tier app, with the full retention feature set, multiple integrations, and complete compliance, runs roughly $100,000 to $300,000. A full-scale custom digital banking platform, built from scratch with advanced fraud, AI features, and deep core-banking integration, runs $600,000 and can pass $1,000,000 to $2,000,000 for the largest programs.

    Inside those totals, three line items dominate: security (around a fifth of the budget), regulatory compliance ($30,000 to $100,000), and integrations with core banking and payment systems. None of these are safe places to cut, because they are exactly what makes the app usable and legal.

    The most useful thing you can do for your budget is scope the compliance and integrations early. That is where mobile banking app development costs are made or blown, and an honest partner will tell you which cost band your requirements fall into before you commit rather than discovering it mid-build.

    How long does it take to build a mobile banking app?

    Timelines track complexity, not ambition. A clickable prototype can be ready in one to two months. A production MVP typically takes four to six months. A full-featured, fully compliant banking app usually runs eight to twelve months or more, and a large in-house custom platform can stretch to eighteen months and beyond.

    The parts that extend timelines are rarely the screens. They are the security hardening, the compliance certification, the core-banking integration, and the testing that a financial app demands before it can touch real money. Rushing these is how projects fail, so a realistic schedule builds them in rather than treating them as a final sprint.

    A good partner defines milestones in discovery so you have an honest schedule before building starts, and ships in visible iterations rather than disappearing into a long black box.

    Native or cross-platform for a banking app?

    This is one of the most common questions in mobile banking app development, and the answer depends on your priorities.

    Cross-platform frameworks like React Native and Flutter let you build for iOS and Android from one codebase, which roughly halves build and maintenance cost and speeds up delivery. For most banking apps, where the feature set is shared across platforms, this is the pragmatic default in 2026.

    Native development, with Swift for iOS and Kotlin for Android, is worth it when you need the deepest device-level security features, the highest performance, or platform-specific capabilities that a cross-platform layer cannot reach cleanly. Some banks choose native specifically for the tightest control over security primitives.

    Mobile banking app development The honest guidance is that cross-platform is the right call for the majority of banking apps, and native is the right call when security depth or performance genuinely demands it. A good team recommends based on your requirements, not on what it prefers to build.

    The mobile banking app development process

    Building a banking app is a staged exercise, and the order matters because each stage de-risks the next.

    Discovery and compliance scoping comes first: map the features, the core-banking integration, the regulatory regime, and the security requirements. This is where the true scope, and the honest cost, becomes visible.

    Design follows, turning real customer workflows into an interface that is fast and trustworthy, because in banking, a confusing screen erodes the trust the whole product depends on. Then development builds the app, the backend, the integration layer, and the security controls in parallel, with security written in rather than bolted on.

    Security testing and compliance certification is a dedicated phase, not an afterthought: penetration testing, code review, and the audits required to satisfy PCI DSS and regional regulators. Finally, deployment and ongoing support: launch, monitor, and maintain, because a banking app is a living product that must stay patched and compliant for years.

    The team behind a banking app

    A serious mobile banking app development effort needs more than app developers. It needs mobile engineers for iOS and Android, backend engineers for the integration and API layer, a security specialist who owns encryption and threat modeling, a compliance lead who knows PCI DSS and regional rules, a UX designer who understands financial workflows, and QA engineers who test against real-world attack scenarios.

    You rarely need all of these full-time from day one, which is why many banks and fintechs work with an experienced custom software development partner who brings the security and compliance expertise that is hardest to hire, or hire mobile developers to extend an existing team. The point is that a banking app is a multi-disciplinary build, and treating it as just “an app” is how the security and compliance gaps appear. The teams that ship successful banking apps staff for the invisible work first, because that is where the product actually lives.

    Integrations a banking app needs

    An app is only as useful as what it connects to. Mobile banking app development almost always involves several integrations, and each one is a place where reliability and security are won or lost.

    The core banking system is the foundation: the app reads and writes real account data through it, usually via a secure API layer rather than talking to it directly. Payment processing and card networks handle transactions and card controls. KYC and identity providers handle onboarding and verification. And increasingly, open banking APIs connect the app to other financial institutions for account aggregation and payments.

    Each integration carries its own security and compliance weight, which is why the integration layer, not the UI, is usually where most of the real engineering time goes.

    Why banking apps fail, and how to avoid it

    Most banking-app trouble is predictable, and nearly all of it traces back to underestimating the hard parts.

    The first mistake is treating security and compliance as a later phase. Retrofitting encryption, fraud detection, and PCI controls into a finished app costs far more than building them in, and it often forces a redesign. Security scoped late is security done twice.

    The second is pricing screens instead of integrations and compliance. The visible app is the cheap part; the core-banking integration, the security layer, and the regulatory work are where the effort and the budget live. A quote that ignores them will be wrong.

    The third is neglecting the boring reliability work, offline handling, error states, and performance under load, in a product where a failed transaction is not a minor bug but a broken trust. The fourth is shipping and stopping: a banking app needs continuous maintenance to stay patched, compliant, and ahead of new fraud patterns.

    How to choose a mobile banking app development company

    The right partner talks about your security, compliance, and integrations before it talks about screens. That is the fastest signal that they have built financial software before.

    Look for real experience with core-banking integration, a documented security and compliance track record, and a support model that lasts beyond launch. Ask how they handle PCI DSS and fraud detection, and how they test against real attack scenarios, because a team that has shipped banking apps will have clear answers.

    Be cautious of quotes that price only the visible app, and of anyone who promises a fully compliant banking app on a consumer-app budget and timeline. Ownership matters too: you should own the code, the infrastructure, and the roadmap, with no lock-in.

    What customers expect from a banking app in 2026

    Customer expectations have moved, and mobile banking app development has to move with them or the app feels dated on launch day.

    The clearest shift is toward intelligence. Users now expect AI-powered spending insights, categorized transactions, and proactive alerts that tell them something useful before they ask. A banking app that only shows a list of transactions feels like a statement; one that explains where the money went feels like a tool.

    Personalization and speed are the next expectations. People want biometric login that just works, instant P2P payments, real-time notifications, and card controls they can act on in one tap, like freezing a lost card immediately. Every extra second or step in these core flows is a reason to abandon the app.

    Open banking is reshaping the baseline too. Customers increasingly expect to see and move money across institutions from one app, which means open banking API strategy is now part of serious banking-app planning rather than a future nice-to-have. Accessibility and multi-language support round out the modern baseline, because a banking app that excludes users is both a business miss and, in many regions, a compliance one.

    The takeaway is that the bar for a competitive banking app keeps rising, and the apps that win treat these expectations as core scope rather than a later upgrade.

    A quick example: what a banking build looks like

    Consider a regional bank that wants a modern app for its retail customers. It needs balances and transactions, transfers and bill pay, card controls, biometric login, real-time fraud alerts, and integration with its existing core banking system, all under PCI DSS and local regulation.

    The scope decisions follow directly. Cross-platform on React Native to serve iOS and Android cost-effectively. A secure API layer between the app and the core banking system so the app never touches it directly. Biometric authentication and MFA built against open standards. Encryption everywhere, fraud monitoring in real time, and a compliance workstream running in parallel from day one.

    Notice what drove every decision above: not the number of screens, but the systems the app had to connect to and the rules it had to satisfy. Change the core banking platform or the regulatory regime and the estimate changes with it. The screens were the fastest part to build and the least important to the outcome.

    On these requirements the project lands in the mid-to-upper cost band, and the integration, security, and compliance work, not the screen count, is what sets the price and the timeline. That is mobile banking app development in one concrete picture: the app is the easy part, and the trust underneath it is the real product.

    Frequently asked questions

    What is mobile banking app development?

    Mobile banking app development is the process of designing, building, securing, and maintaining a mobile app that lets customers manage money, connected in real time to a core banking system, and built to meet strict security and regulatory requirements like PCI DSS.

    How much does it cost to build a mobile banking app in 2026?

    A basic secure MVP starts around $45,000 to $80,000, a mid-tier app with full features and compliance runs about $100,000 to $300,000, and a full custom digital banking platform runs $600,000 and up. Security takes roughly a fifth of the budget and compliance adds $30,000 to $100,000.

    How long does it take to develop a mobile banking app?

    A prototype takes one to two months, a production MVP four to six months, and a full-featured compliant app eight to twelve months or more. Security hardening, compliance certification, and core-banking integration are what extend the timeline.

    How secure are mobile banking apps?

    Well-built banking apps are very secure because security is engineered in: biometric authentication, multi-factor authentication, end-to-end encryption, certificate pinning, jailbreak and root detection, and real-time fraud monitoring. The risk comes from apps where security was added late rather than designed in.

    What features should a mobile banking app have?

    Core features are balances, transaction history, transfers, bill pay, and card management. High-retention features are biometric login, real-time transaction alerts with card controls, instant P2P payments, AI spending insights, and in-app support, all wrapped in a strong security layer.

    What compliance does a banking app need?

    Typically PCI DSS for card data, plus regional rules such as PSD2 in Europe, GDPR for personal data, and KYC and AML for identity and anti-fraud. Compliance adds $30,000 to $100,000 and must be built in from the start, not retrofitted.

    Should a banking app be native or cross-platform?

    Cross-platform with React Native or Flutter is the pragmatic default for most banking apps because one codebase for iOS and Android roughly halves cost. Native is worth it when you need the deepest device-level security or maximum performance.

    How do you choose a mobile banking app development company?

    Choose one that scopes your security, compliance, and core-banking integration before pricing screens, has documented financial-software experience, tests against real attack scenarios, supports the app beyond launch, and hands you full ownership of the code and infrastructure.

    Build a banking app your customers can trust

    Mobile banking app development succeeds or fails on the parts users never see: the security, the compliance, and the integrations. If you are scoping a banking app and want an honest read on cost, timeline, and what production really requires, talk to Mobilions. Senior engineers who build fintech and mobile apps scope it, build it, secure it, and support it in production, with the security and compliance planned from the first day rather than discovered on the last.

  • Grocery Delivery App Development: A Complete 2026 Guide

    Grocery Delivery App Development: A Complete 2026 Guide

    Grocery delivery app development in 2026 is not one app, it is a system: a customer app, a shopper or driver app, and an admin dashboard, usually connected to store inventory. A basic single-store MVP runs roughly $25,000 to $60,000 over 2 to 4 months. A real multi-store or quick-commerce platform (Instacart-style) with routing, inventory sync, and dark-store fulfilment runs $150,000 to $500,000 and up, over 5 to 9 months. The market is huge and growing fast (online grocery is close to $0.9 trillion in 2026), but the hard part is operations, real-time tracking, substitutions, and delivery logistics, not the shopping screens. Start with one model and one region, get the operations right, then scale.

    Grocery delivery app development looks like building a shopping app with a delivery button, and that misunderstanding is exactly why so many of these projects blow their budgets. What you are actually building is a small logistics company that happens to have an app on top. The catalogue and cart are the easy part. Keeping inventory accurate, routing drivers, handling out-of-stock substitutions, and tracking an order in real time is where the real engineering and the real cost sit.

    This guide is the practical version for founders, retailers, and startups. It covers what grocery delivery app development actually involves, whether the 2026 market is worth entering, the business models to choose from, the features each app needs, honest cost and timeline ranges, the parts that are genuinely hard, how to monetize, and how to pick a team. We build delivery and marketplace apps at Mobilions, so this is a builder’s view with real numbers, not a brochure.


    What grocery delivery app development actually involves

    Before any pricing makes sense, you need to see the full system, because the cost comes straight from it. A working grocery delivery product is at least three connected apps plus a backend.

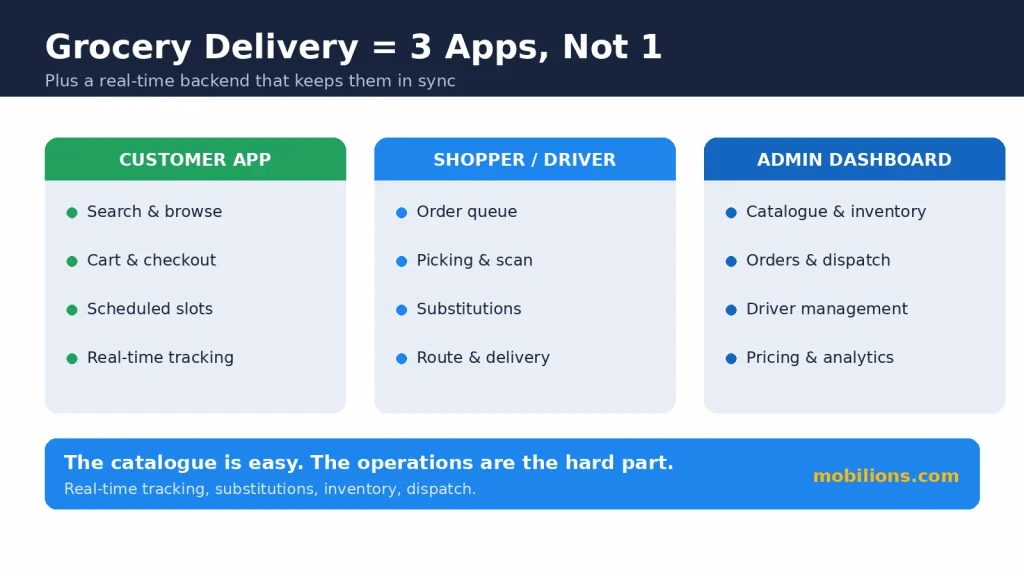
    Grocery delivery app development: the three apps, customer, shopper/driver, and admin dashboard

    There is the customer app (browse, search, cart, pay, track), the shopper or driver app (accept orders, pick items, handle substitutions, navigate, deliver), and the admin dashboard (catalogue, inventory, orders, drivers, pricing, analytics). Underneath sits a backend that ties them together in real time, plus integrations with payments, maps and routing, notifications, and often a store or POS system for live inventory. Depending on your model, you may also need a store-partner interface and a dark-store or warehouse workflow.

    That is why grocery delivery costs more than a typical app. You are not building one screen flow; you are building three coordinated apps and the real-time operations engine that keeps them in sync. Get that engine right and the business works. Get it wrong and you have a pretty catalogue that cannot actually fulfil an order.

    Is a grocery delivery app worth building in 2026?

    The market case is strong, with an important caveat about where the difficulty lives. Online grocery is one of the largest and fastest-growing digital markets: it sits close to $0.9 trillion globally in 2026 and is projected to keep growing at more than 20 percent a year, according to market research. Quick commerce, the 15-to-30-minute delivery model, is growing even faster, and grocery is its anchor category. Dark stores, small local fulfilment hubs, are expanding rapidly to make that speed possible.

    So the demand is real and rising. The caveat is that this is an operationally hard, thin-margin business dominated by well-funded players, and the winners compete on fulfilment speed, accuracy, and unit economics, not on app design. A grocery delivery app is worth building if you have a genuine edge, a store network, a region the incumbents serve poorly, a niche (organic, ethnic, bulk), or a fulfilment advantage, and it is a hard place to be without one. Build for the operations, not just the app.

    The main business models

    Your model decides your architecture and your cost, so choose it deliberately before you build. There are four common ones.

    Multi-vendor marketplace (Instacart-style): you connect many stores and shoppers to customers without owning inventory. Widest reach, most complex to build, because you are coordinating many partners, shoppers, and catalogues.

    Single-store or chain app: a retailer’s own delivery app for its own stores and inventory. Simpler and the most common starting point for an existing grocery business.

    Quick-commerce / dark store: you own small local fulfilment hubs and promise very fast delivery (15 to 30 minutes). Operationally intense and capital-heavy, but the fastest-growing model.

    Hyperlocal / store-fulfilled: you use existing stores as fulfilment points, which is how large retailers have scaled delivery cheaply. A pragmatic middle path.

    Most new entrants should start with the narrowest model that fits their real advantage, usually a single-store or single-region app, prove the operations, and expand. Trying to launch a full multi-vendor marketplace as a first product is the classic way to run out of money before the operations work.

    Must-have features, app by app

    Scope drives cost, so it helps to separate the essentials for each app from the extras.

    Customer app (essential): smart product search and browse, cart and checkout, multiple payment options, scheduled delivery slots, real-time order tracking, order history and reorder, and substitution preferences. Shopper/driver app (essential): order queue, in-store picking list, barcode or item scan, substitution handling with customer approval, route navigation, and proof of delivery. Admin dashboard (essential): catalogue and inventory management, order and dispatch management, driver management, pricing and promotions, and analytics.

    Nice-to-have and differentiating features, AI personalization, demand forecasting, loyalty and subscriptions, multi-language, and advanced route optimization, matter, but they come after the core three-app loop works end to end. The mistake is padding the customer app with features while under-building the shopper and admin sides, which is where fulfilment actually happens.

    AppCore jobWatch out for
    CustomerBrowse, order, trackReal-time tracking, substitutions
    Shopper / driverPick, substitute, deliverPicking flow, routing, offline areas
    AdminCatalogue, orders, driversLive inventory sync, dispatch logic

    How much does grocery delivery app development cost?

    Here are honest 2026 ranges. They are wide because “grocery delivery app” spans a single-store MVP and a national marketplace.

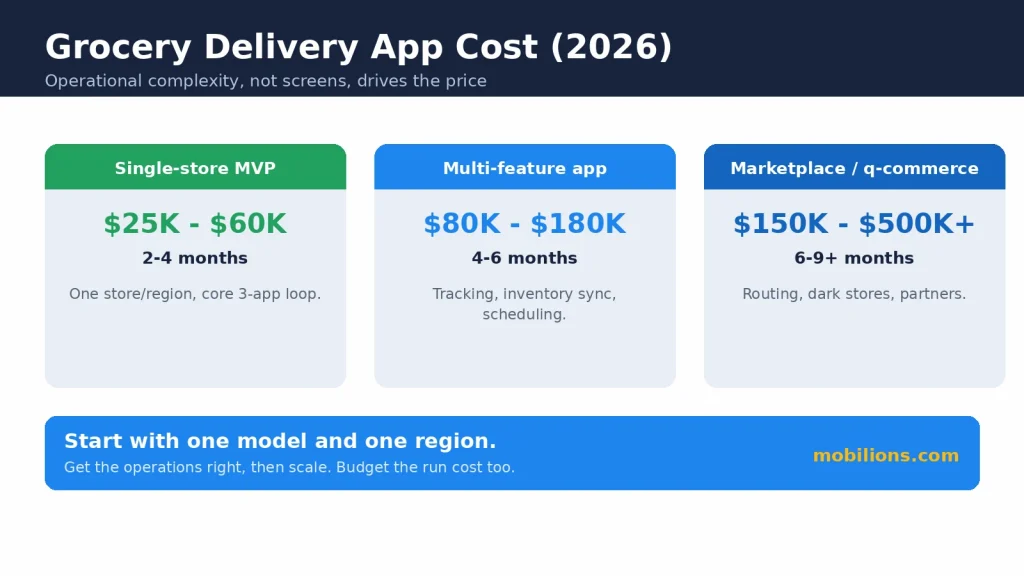
    Grocery delivery app development cost 2026: single-store MVP, multi-feature, and marketplace tiers

    A basic single-store MVP (one store or region, core customer app plus a simple driver and admin flow) runs roughly $25,000 to $60,000 over 2 to 4 months. A solid multi-feature app with real tracking, inventory sync, scheduling, and a proper admin runs $80,000 to $180,000. A multi-store or quick-commerce platform with routing, dark-store workflows, and partner systems runs $150,000 to $500,000, and a large enterprise marketplace can exceed $1,000,000. The single biggest cost driver is not the customer app; it is the operational complexity, routing, real-time inventory, multi-party coordination, behind it.

    Then there are the ongoing costs founders miss: maintenance (roughly 15 to 20 percent of build per year), backend and hosting that must scale with orders, third-party services (maps, payments, SMS, push), app store fees, and the operational cost of running deliveries themselves. An app is the smaller line item; running the operation is the bigger one. Budget for both from the start.

    How long does it take?

    Timeline tracks model and scope closely. A single-store MVP typically takes 8 to 16 weeks. A full multi-feature app runs 4 to 6 months. A multi-store or quick-commerce platform runs 6 to 9 months or more. Those windows assume a locked scope and a single model to start; the fastest way to overrun is to try to build every model and feature at once. A good team will push you to launch a focused first version in one region so you can learn the operations before scaling them.

    How it is built: the tech behind it

    A quick, non-technical picture of the moving parts, because it explains where the effort goes. The apps are usually built cross-platform (Flutter or React Native) to reach iOS and Android efficiently, on top of a backend that handles orders, users, and real-time state. Real-time tracking uses live location and websockets so the customer sees the driver move.

    Payments run through a provider like Stripe rather than being built from scratch. Routing and navigation use a maps platform such as Google Maps Platform for driver directions and delivery estimates. And inventory either lives in your admin or syncs from a store or POS system so the catalogue reflects what is actually in stock.

    The engineering value is in wiring these together reliably under real order volume, which is exactly the part that is easy to underestimate.

    The parts that are genuinely hard

    It is worth naming where projects actually struggle, because that is where your budget and your team’s quality really matter.

    Real-time tracking that stays accurate as drivers move through dead zones is harder than it looks. Substitutions, an item is out of stock, the shopper needs a fast, clear way to offer an alternative and get approval, are a constant source of customer frustration when done badly. Live inventory that reflects reality prevents the worst experience of all, ordering something that is not there. Routing and dispatch, assigning orders to the right driver and sequencing deliveries efficiently, is a genuine optimization problem at scale.

    And peak load, everyone orders at similar times, means the system has to hold up when it matters most. These are the difference between an app that demos well and one that runs a real operation, and they are where an experienced team earns its fee.

    How to monetize a grocery delivery app

    Revenue comes from several levers, and most platforms combine them. Delivery fees and service fees on each order are the direct model. Markups on product prices are common in marketplaces. Subscriptions (a membership for free or cheaper delivery) improve retention and are widely used by the leaders. Commissions from partner stores apply in marketplace models. And in-app advertising or promoted products become a real revenue line at scale. The honest point about grocery is that margins are thin, so the model has to be designed carefully around real unit economics, what it actually costs you to fulfil an order, rather than assumed. A beautiful app with negative unit economics is not a business.

    Why grocery delivery apps fail

    Most failures are not about the app; they are about the operation and the economics. The common patterns: launching too broad (many stores or the whole city) before the fulfilment works, so quality collapses; ignoring unit economics until the delivery costs eat the revenue; under-building the shopper and admin sides so orders cannot be fulfilled smoothly; poor inventory accuracy that leads to constant substitutions and refunds; and competing on app features against incumbents who compete on speed and price.

    The fixes are consistent: start narrow, get the operations and the numbers right in one region, build the fulfilment side as seriously as the customer side, and expand only from evidence. Treating this as an app project rather than an operations business is the root mistake.

    How to choose a development company

    Because the operational engine decides success, pick a team that has built one before. Look for a partner with real delivery, logistics, or marketplace experience (ask to see comparable apps they have shipped), an MVP-first, one-model-first process rather than a push to build everything, transparent pricing with a clear scope, and honest answers about the operational hard parts, not just the screens. Confirm what is included (the three apps, backend, integrations, testing, support), who owns the code (you should), and how they handle scaling and maintenance. Red flags: a quote that only prices the customer app, no relevant portfolio, hand-waving about real-time tracking and inventory, or a promise to build a full marketplace fast and cheap.

    How Mobilions helps

    We build delivery and marketplace apps end to end, and we have shipped software since 2016. For grocery, we start by pinning down your model and your real advantage, then build a focused first version, the three-app loop for one store or region, with the operational parts (real-time tracking, substitutions, inventory, dispatch) built properly rather than faked for a demo. We build cross-platform to reach both stores efficiently, integrate payments, maps, and inventory the right way, design around your actual unit economics, and hand you full ownership of the code. We scale it with you once the operation works in one place.

    What we will not do is quote you a cheap customer app and leave the fulfilment side hollow, because that is precisely the app that cannot run a real delivery business.

    The bottom line

    Grocery delivery app development in 2026 is a systems-and-operations build, not a shopping-app build. Budget roughly $25,000 to $60,000 for a single-store MVP, $80,000 to $180,000 for a solid app, and $150,000 to $500,000 or more for a multi-store or quick-commerce platform, and remember the operation costs more to run than the app costs to build. The market is enormous and growing fast, but it is operationally hard and margin-thin, and it rewards fulfilment quality over interface polish.

    Choose one model and one region, build the customer, shopper, and admin apps as one coordinated system, get real-time tracking, substitutions, inventory, and unit economics right, and expand from evidence. Do that, and grocery delivery is a large opportunity. Treat it as an app instead of an operation, and it is an expensive way to learn how hard logistics is.

    If you want a straight estimate and a first-version plan for your specific grocery model, that is exactly the conversation our senior engineers have with founders and retailers every week.

    Book a discovery call for an honest scope and quote, no obligation. You can also explore our mobile app development services and how we work with ecommerce and retail businesses.

    Key takeaways

    • Grocery delivery app development means at least three apps, customer, shopper/driver, and admin, plus a real-time backend and store integrations, not a single shopping app.
    • A single-store MVP runs about $25,000 to $60,000 (2 to 4 months); a multi-store or quick-commerce platform runs $150,000 to $500,000+ (6 to 9 months).
    • The market is huge and fast-growing (online grocery near $0.9 trillion in 2026, quick commerce growing even faster), but it is operationally hard and margin-thin.
    • Choose a model first, multi-vendor marketplace, single-store, quick-commerce/dark store, or hyperlocal, and start with the narrowest one that fits your advantage.
    • The hard parts are real-time tracking, substitutions, live inventory, routing/dispatch, and peak load, not the shopping screens; build the shopper and admin sides as seriously as the customer app.
    • Monetize through delivery and service fees, markups, subscriptions, commissions, and ads, but design around real unit economics because margins are thin.
    • Most failures come from launching too broad, ignoring unit economics, and under-building fulfilment; start narrow, get one region right, and scale from evidence.

    Frequently asked questions

    How much does it cost to build a grocery delivery app in 2026?

    A basic single-store MVP runs about $25,000 to $60,000 over 2 to 4 months. A solid multi-feature app with real tracking, inventory sync, and a proper admin runs $80,000 to $180,000, and a multi-store or quick-commerce platform runs $150,000 to $500,000 or more. The biggest cost driver is operational complexity, routing, real-time inventory, multi-party coordination, not the customer-facing screens, and you should also budget ongoing maintenance and operating costs.

    How long does it take to develop a grocery delivery app?

    A single-store MVP typically takes 8 to 16 weeks, a full multi-feature app takes 4 to 6 months, and a multi-store or quick-commerce platform takes 6 to 9 months or more. These assume a locked scope and one model to start. Trying to build every model and feature at once is the main cause of overruns, so launching a focused first version in one region is the fastest route.

    How many apps do I need for a grocery delivery service?

    At least three: a customer app (browse, order, track), a shopper or driver app (pick, substitute, navigate, deliver), and an admin dashboard (catalogue, inventory, orders, drivers). Depending on your model you may also need store-partner interfaces or a dark-store workflow. They are tied together by a real-time backend, and under-building the shopper and admin sides is a common, costly mistake.

    What features does a grocery delivery app need?

    The customer app needs search, cart and checkout, multiple payments, scheduled slots, real-time tracking, and substitution preferences. The driver app needs an order queue, picking list, substitution handling, navigation, and proof of delivery. The admin needs catalogue and inventory management, order and dispatch control, driver management, pricing, and analytics. AI personalization and route optimization are valuable additions once the core loop works.

    What business model should I choose?

    The main options are a multi-vendor marketplace (Instacart-style), a single-store or chain app, a quick-commerce dark-store model (15 to 30 minute delivery), or a hyperlocal store-fulfilled model. Most new entrants should start with the narrowest model that fits their real advantage, usually single-store or single-region, prove the operations, then expand. Launching a full marketplace as a first product is the classic way to run out of money.

    Is a grocery delivery app a good business in 2026?

    The market is large and growing fast, online grocery is near $0.9 trillion in 2026 and quick commerce is growing even quicker, so demand is real. But it is operationally hard, margin-thin, and dominated by well-funded players who compete on fulfilment speed and unit economics, not app design. It is a good business only if you have a genuine edge: a store network, an underserved region, a niche, or a fulfilment advantage.

    What makes grocery delivery apps technically hard?

    The hard parts are real-time driver tracking that stays accurate through dead zones, fast and clear substitution handling when items are out of stock, live inventory that reflects reality, routing and dispatch that assign and sequence deliveries efficiently, and holding up under peak order load. These operational systems, not the shopping screens, are where projects struggle and where an experienced team makes the difference.

    How do grocery delivery apps make money?

    Through delivery fees, service fees, markups on product prices, subscriptions (memberships for free or cheaper delivery), commissions from partner stores in marketplace models, and in-app advertising or promoted products at scale. Because grocery margins are thin, the model must be designed around real unit economics, what it actually costs to fulfil an order, rather than assumptions. A polished app with negative unit economics is not a viable business.

    Should I build native or cross-platform?

    Most grocery delivery apps are built cross-platform (Flutter or React Native) so the customer, driver, and admin apps reach iOS and Android efficiently without doubling the cost. Cross-platform performance is more than adequate for these apps, and it lets you get the whole three-app system to market faster, which matters more here than squeezing out native performance you do not need at launch.

    How do I choose a grocery delivery app development company?

    Look for real delivery, logistics, or marketplace experience (ask to see comparable shipped apps), an MVP-first and one-model-first process, transparent pricing that covers all three apps and the backend, and honest answers about the operational hard parts. Confirm what is included, who owns the code (you should), and how they scale and maintain it. Watch for quotes that price only the customer app or promise a full marketplace fast and cheap.

    Does Mobilions build grocery delivery apps?

    Yes. We build delivery and marketplace apps end to end, starting by pinning down your model and advantage, then building a focused first version, the customer, driver, and admin apps as one system, with real-time tracking, substitutions, inventory, and dispatch built properly. We integrate payments, maps, and inventory the right way, design around your unit economics, and hand you full ownership. Book a discovery call for an honest scope and quote.

  • Cloud Cost Optimization: A 2026 Strategy for DevOps and Hybrid Infrastructure

    Cloud Cost Optimization: A 2026 Strategy for DevOps and Hybrid Infrastructure

    Cloud cost optimization is no longer a quarterly cleanup task you hand to the finance team. It is an engineering discipline that decides whether your infrastructure scales profitably or quietly bleeds money every hour it runs. In 2026, the pressure is sharper than it has been in years, and the teams that treat cost as a first-class design constraint are the ones shipping faster and spending less.

    This guide lays out a practical strategy Mobilions uses when we scope, build, and support production systems for clients. It covers where the waste actually hides, how to fix it without slowing delivery, and how DevOps, multi-cloud, and hybrid infrastructure decisions change the math. No theory for its own sake. Just the moves that move the bill.

    Why cloud spend got worse in 2026, not better

    For five straight years, the industry told a comfortable story: cloud waste was falling as teams matured. That story broke in 2026. According to Flexera’s State of the Cloud report, wasted cloud spend climbed back to roughly 29 percent, reversing a half-decade of steady decline.

    Chart showing where cloud spend leaks in 2026 for cloud cost optimization by Mobilions

    The reason is not that engineers forgot how to optimize. It is that the workloads changed faster than the governance around them. AI moved from experiment to production, and it brought expensive hardware with it.

    Only about 2 percent of CIOs report spending less on cloud than they projected. For almost everyone else, overspend is the default state, not the exception. As footprints grow, complexity grows faster than the discipline needed to control it, which is exactly why cloud cost optimization has become an engineering priority rather than an afterthought.

    Two culprits dominate the waste. Idle compute accounts for around 35 percent of it, and overprovisioned instances for another 25 percent. In plain terms, most organizations are paying for capacity that either sits still or was sized for a peak that rarely arrives.

    Then there is the newest line item. GPUs now make up close to 18 percent of spend at AI-forward organizations, up from about 4 percent in 2023. Statically provisioned GPU fleets often run at just 30 to 40 percent utilization, which means more than half of that premium hardware is burning money while it waits for work. That idle premium hardware is now one of the biggest targets for cloud cost optimization in 2026.

    What cloud cost optimization actually means

    Cloud cost optimization is the ongoing practice of matching what you pay to the value you get, without sacrificing performance, reliability, or delivery speed. It is not about switching everything off or picking the cheapest region and hoping for the best.

    Done well, it answers three questions continuously. What are we running, and does it earn its keep? Are we buying it the smartest way? And who is accountable when a number moves the wrong direction?

    The industry name for this discipline is FinOps, and the FinOps Foundation frames it around three phases that run in parallel rather than in sequence. Inform is about visibility. Optimize is about action. Operate is about making good behavior automatic.

    The phases are not owned by one team. Finance tends to live in Inform. Engineering tends to live in Optimize. Leadership tends to live in Operate. The point is that everyone is working the same problem from a different angle at the same time.

    The strategy: five layers that compound

    The mistake most teams make is chasing one tactic, like buying reserved capacity, and calling it a program. Real savings come from layering moves that reinforce each other. Here is the order we recommend, because each layer makes the next one cheaper and safer.

    Layer 1: See the money before you touch it

    You cannot optimize what you cannot attribute. The first layer is visibility, and it starts with tagging. Every resource needs an owner, an environment, and a cost center attached to it, enforced at deploy time rather than begged for after the fact.

    This matters more than it sounds. A striking 74 percent of organizations that already own cloud cost tools say they lack the time or people to act on the recommendations those tools produce. Visibility without accountability just generates dashboards nobody reads.

    Tie every major service to a unit metric that the business understands. Cost per active user, cost per transaction, cost per model inference. When spend is expressed in units the business cares about, a rising bill becomes a conversation instead of a surprise.

    Layer 2: Right-size and kill the idle

    With attribution in place, the fastest wins are almost always right-sizing and shutting down waste. Idle and oversized resources are the single largest source of cloud waste, so this is where the early return lives.

    Right-sizing means analyzing real usage and resizing compute, memory, and storage tiers to fit it. A database provisioned for a launch-day spike two years ago is probably three sizes too big today. Storage that was hot when it was written is probably cold now and belongs in a cheaper tier.

    Killing the idle means non-production environments that sleep on nights and weekends, orphaned volumes and load balancers nobody deleted, and snapshots that outlived their purpose. None of this is glamorous. All of it is free money.

    Layer 3: Buy compute the smart way

    Once your footprint reflects real demand, you can commit to it confidently. This is where pricing models do the heavy lifting, and the discounts are large enough to change a P&L.

    On-demand, reserved, and spot instances compared for cloud cost optimization by Mobilions

    Reserved Instances and equivalent commitments deliver roughly 30 to 70 percent off standard rates in exchange for a one to three year commitment. Savings Plans on AWS run from about 40 to 72 percent while letting you change instance families and mix compute types. On Google Cloud, one-year commitments reach around 57 percent and three-year terms up to 70 percent.

    Spot capacity is the other lever. It uses a provider’s spare capacity at 60 to 80 percent off, with the catch that it can be reclaimed at short notice. That makes it ideal for fault-tolerant, interruptible work like batch jobs, CI pipelines, and stateless processing.

    The practical playbook is to reserve 60 to 70 percent of your steady-state baseline, then handle peaks with autoscaling groups that mix on-demand and spot. Aim for a commitment coverage ratio of 60 to 75 percent. Most teams end up with a blended effective discount of 35 to 50 percent once you account for partial coverage and the on-demand spikes.

    Layer 4: Automate optimization into the pipeline

    Manual optimization does not survive contact with a fast-moving engineering team. The fourth layer is making the right choice the automatic one, which is where DevOps and cloud cost optimization become the same conversation.

    Autoscaling should be the default, not a special case, so capacity tracks demand instead of sitting parked at peak. Cost checks belong in CI/CD, where a pull request that doubles the projected monthly cost gets flagged before it merges, not after the invoice arrives. Tools like Infracost do exactly this, showing the cost impact of a change inside the pull request.

    Infrastructure as code makes this enforceable. When environments are defined in version control, you can bake in guardrails: no untagged resources, no oversized defaults, no public storage by accident. Policy becomes code, and drift becomes visible.

    Layer 5: Govern it as a habit

    The final layer is the Operate phase in practice. Anomaly detection catches a runaway job or a misconfigured autoscaler within hours instead of at month-end. Budgets and alerts route to the team that owns the spend, not to a central inbox.

    Maturity shows up in the numbers. Organizations without a real FinOps program waste somewhere between 32 and 40 percent of their cloud spend. Teams at the mature end bring that down to 15 to 20 percent, and the most disciplined get idle waste closer to 14 percent. That gap is the prize.

    Kubernetes and containers: where waste hides in plain sight

    Containers promised efficiency, and they can deliver it, but only with active management. Left alone, Kubernetes is one of the most reliable ways to overpay.

    The data is sobering. Average CPU utilization across tens of thousands of production clusters sits around 8 percent before any optimization is applied. Teams request far more than they use, because requesting generously feels safer than getting paged.

    The fix is a combination of honest resource requests, bin-packing workloads onto fewer nodes, and autoscaling at both the pod and node level. Set requests from observed usage, not from guesses, and let the cluster scale down when the work is gone.

    Do this and the savings are structural, not one-time. A cluster running at 45 to 60 percent utilization instead of 8 percent is doing the same work on a fraction of the machines, every hour, forever.

    The AI cost problem you cannot ignore

    AI workloads have rewritten the cost conversation, and every serious cloud cost optimization strategy in 2026 has to account for them. Nearly all FinOps teams, around 98 percent, now manage AI spend, up from roughly 63 percent a year earlier.

    The core issue is GPU utilization. Measured across more than 20,000 clusters, average enterprise GPU utilization has been reported as low as 5 percent. You are renting the most expensive hardware in the building and using a sliver of it.

    The answers borrow from everything above and add a few specifics. Schedule GPU work so fleets stay busy instead of idling between jobs. Right-size to the smallest accelerator that meets the latency target. And measure cost per inference, not just cost per hour, because that is the number that tells you whether a feature pays for itself.

    The upside is real. Disciplined AI cost programs have driven cost-per-answer down dramatically in production deployments, in some analyses from cents per response to a fraction of that. The efficiency was always there. It just had to be scheduled and measured.

    Multi-cloud, hybrid cloud, and the placement decision

    Where a workload runs is a cost decision as much as a technical one, and this is where multi-cloud and hybrid strategies earn their reputation, for better and worse.

    Multi-cloud gives you leverage and resilience, but it introduces a tax that surprises teams: egress. Standard internet egress on the major hyperscalers runs about $0.087 to $0.12 per gigabyte, and moving data between providers means paying to get it out. For data-heavy applications, cross-cloud transfer can quietly rival compute in cost.

    Hybrid cloud takes a different angle. It keeps high-volume, predictable, or sensitive data in a private environment and bursts only specific workloads to public cloud when elasticity is genuinely needed. Done right, it sidesteps a lot of egress and gives you predictable pricing on the steady-state core.

    The placement question is why hybrid keeps gaining ground. By some counts, 37 percent of enterprises have moved at least one workload from public cloud back to private infrastructure in the past two years, up from 14 percent in 2022. The average repatriated workload saves around 32 percent of its annual cost after hardware is amortized.

    The lesson is not “leave the cloud.” It is that workload placement is a dynamic decision. Elastic and spiky work belongs on hyperscaler compute. Steady, heavy, latency-sensitive, or compliance-bound work often runs cheaper and just as well on private or colocated infrastructure. The winning architectures treat placement as something you revisit, not something you decided once during migration.

    A quick example: what this looks like in practice

    Consider a mid-sized SaaS product running a predictable API tier, a spiky background-processing tier, and a growing AI feature. Before optimization, everything runs on-demand, the Kubernetes cluster sits at single-digit utilization, and a GPU node runs 24/7 for a feature used mostly during business hours.

    The strategy applies in order. Tagging reveals the AI feature is a third of the bill. Right-sizing shrinks the oversized API instances and the cluster consolidates onto fewer nodes. The steady API baseline moves to a one-year Savings Plan at roughly half price, while background jobs move to spot capacity at a deep discount.

    The GPU node gets scheduled to match real demand instead of running around the clock, and cost is now tracked per inference. Anomaly alerts route to the owning team, and a cost check in CI flags any change that spikes the projection.

    None of these moves is exotic. Stacked together, they routinely take a 25 to 40 percent bite out of a bill while making the platform more predictable, and that is the entire point of a real cloud cost optimization strategy: durable savings that do not cost you delivery speed.

    A 90-day rollout plan

    You do not need a year to see results. A focused quarter, run in the right order, gets most teams from surprise bills to a controlled, predictable spend.

    Days 1 to 30: see everything

    Spend the first month on visibility and quick wins. Enforce tagging at deploy time, connect a cost tool, and map spend to the teams and features that create it.

    While the tags settle, take the free money. Shut down idle non-production environments overnight, delete orphaned volumes and snapshots, and move cold storage to cheaper tiers. These moves carry almost no risk and usually pay for the whole exercise on their own.

    Days 31 to 60: right-size and commit

    With clean attribution, right-size compute, memory, and storage against observed usage. Resist the urge to buy commitments until the footprint reflects real demand, because reserving oversized capacity just locks in the waste.

    Once the baseline is honest, buy it the smart way. Put a one-year Savings Plan or reservation under your steady-state load, move interruptible work to spot capacity, and set your coverage ratio in the 60 to 75 percent range.

    Days 61 to 90: automate and govern

    The last month makes the gains permanent. Turn on autoscaling by default, add a cost check to your CI/CD pipeline, and route anomaly alerts to the teams that own the spend.

    Finish by writing the guardrails into infrastructure as code so the next hundred deploys inherit them. After 90 days you should have visibility, a right-sized footprint, committed discounts, and automation that keeps all three from drifting.

    Common mistakes that quietly inflate the bill

    The first mistake is optimizing once. Cloud spend drifts the moment you look away, because every deploy adds resources and few remove them. Optimization is a loop, not a project.

    The second is buying commitments before right-sizing. Lock in a three-year reservation on an oversized fleet and you have just guaranteed three years of overpaying. Fix the footprint first, then commit to it.

    The third is treating cost as finance’s job. Engineers make the decisions that create the spend, so they have to see the price of those decisions in the tools they already use. Cost visibility that never reaches the people who cause the cost changes nothing.

    The fourth is ignoring the boring line items. Egress, idle non-production environments, forgotten storage, and orphaned resources rarely show up in a single alarming number. They add up to a large one.

    How Mobilions approaches cloud cost optimization

    We build and support production software, so we treat cost as an engineering property from day one rather than a cleanup phase after launch. That means tagging and unit metrics are part of the initial architecture, not a retrofit.

    Our engineers scope workloads against real demand, choose pricing models deliberately, and bake autoscaling and cost guardrails into the delivery pipeline. When a hybrid or multi-cloud split saves money without adding fragility, we design for it. When it just adds egress and complexity, we say so.

    The result our clients care about is simple. The systems we ship run predictably, scale when they need to, and do not surprise anyone at the end of the month. That is what good cloud cost optimization buys you: room to grow without the bill growing faster than the business.

    Frequently asked questions

    What is cloud cost optimization?

    Cloud cost optimization is the continuous practice of aligning what you spend on cloud infrastructure with the value it delivers, without hurting performance or reliability. It combines visibility, right-sizing, smart purchasing, automation, and governance so you pay for what you actually use.

    How much can cloud cost optimization save?

    It depends on your starting maturity. Organizations without a structured program typically waste 32 to 40 percent of cloud spend, while disciplined teams bring waste down to 15 to 20 percent. A focused first pass with right-sizing and commitment purchases often reduces a bill by 25 to 40 percent.

    What is the difference between FinOps and cloud cost optimization?

    Cloud cost optimization is the set of technical and financial actions that reduce waste. FinOps is the operating model and culture that makes those actions continuous and shared across engineering, finance, and leadership. FinOps is the framework, optimization is the work it drives.

    When should I use reserved instances versus spot instances?

    Use reserved instances or savings plans for steady, predictable baseline workloads you will run for a year or more, since they trade commitment for 30 to 70 percent discounts. Use spot instances for interruptible, fault-tolerant work like batch jobs and CI, where 60 to 80 percent savings outweigh the risk of reclamation.

    Does multi-cloud reduce or increase costs?

    It can do either. Multi-cloud improves leverage and resilience, but it adds egress and operational complexity that can erase the savings for data-heavy workloads. It reduces cost only when placement is deliberate and cross-cloud data movement is kept low.

    Is hybrid cloud cheaper than public cloud?

    For predictable, high-volume, or compliance-bound workloads, hybrid or private infrastructure is often cheaper because pricing is stable and egress is minimized. For spiky, elastic workloads, public cloud usually wins. The cheapest answer is usually a hybrid split that matches each workload to the right home.

    How do AI and GPU workloads change cloud cost strategy?

    AI concentrates spend in expensive GPUs that frequently run at very low utilization. The strategy adds GPU scheduling to keep fleets busy, right-sizing to the smallest accelerator that meets the target, and measuring cost per inference so you know whether each AI feature pays for itself.

    Who should own cloud cost optimization in a company?

    It is a shared responsibility. Engineering owns the technical decisions that create spend, finance owns forecasting and accountability, and leadership owns the policies and priorities. A FinOps practice or an experienced engineering partner keeps all three aligned.

    Ready to stop overpaying for your infrastructure?

    If your cloud bill is growing faster than your business, the fix is rarely a single switch. It is a strategy applied in the right order by engineers who understand both the systems and the spend. Talk to Mobilions about a cloud cost optimization plan built for how your product actually runs.

  • Fabric Architectures for AI Systems: A Complete 2026 Guide

    Fabric Architectures for AI Systems: A Complete 2026 Guide

    Ask ten engineers what an “AI fabric” is and you’ll get ten answers. One means a data platform. One means the network cabling between GPUs. One means whatever their vendor sold them last quarter. That confusion is the single biggest reason teams struggle to reason about fabric architectures for AI systems, so this guide starts by clearing it up, then goes deep on the version that actually matters when you’re building AI: the software one.

    Here’s the uncomfortable truth underneath the buzzword. Most AI systems that stall in production don’t stall because the model is weak. They stall because the plumbing underneath (the data access, the retrieval, the permissions, the monitoring) was wired together by hand, use case by use case, until nobody could safely change anything. Gartner reported in 2026 that organizations with successful AI initiatives invest up to four times more in their data and analytics foundations than everyone else. A fabric is what that investment looks like when it’s done well.

    What is a fabric architecture for an AI system?

    A fabric architecture for an AI system is a shared software layer that connects data, models, retrieval, orchestration, and governance through consistent interfaces, so the parts of your AI stack work as one system instead of a web of one-off integrations. You connect each component to the fabric once, rather than wiring every component directly to every other one.

    The name is borrowed from textiles on purpose. A fabric is a mesh of threads that behaves like a single continuous surface. Swap one thread and the cloth still holds. In software terms: swap your vector database, add a second model, tighten a permission, and the contract between layers stays put, so you change one connector instead of hunting down fifty call sites across a dozen services.

    It’s worth being precise about what a fabric is not. It isn’t a product you buy, despite what the demos imply, and it isn’t your database or your model. It’s an architectural pattern, a set of clean seams between the moving parts, that you assemble from platforms and glue code. The older enterprise idea of a “data fabric” covers just the data seam. An AI fabric stretches the same discipline across the whole path, from raw data to a governed agent doing real work.

    Why do AI systems end up needing a fabric?

    Because the pieces multiply faster than anyone plans for. A first AI feature usually starts clean: one model, one data source, a hard-coded prompt. It ships, it works, everyone’s happy. Then the second use case wants two more data sources and a cheaper model for the easy requests. The third needs an embedding model and access to a system the first two never touched. Each connection is bespoke, with its own auth, its own retries, its own logging, or no logging at all.

    Six months in, you’ve rebuilt the classic “n-by-m” mess, where every new model or data source multiplies the connections you have to babysit. AI makes this worse than traditional software for three concrete reasons:

    • You rarely end up with one model. A big model for hard reasoning, a small cheap one for classification, an embedding model for search, maybe a fine-tuned one for your domain. Each needs to be called, versioned, and paid for.
    • The inputs are messier than a normal app’s. Documents, databases, APIs, and live streams, all with different formats and freshness, all needing permission checks before a model ever sees them.
    • The system acts, it doesn’t just read. An AI system generates content and takes actions, so weak governance isn’t a tidiness problem, it’s a liability.

    The data problem is the one teams underestimate most. IBM found that only 29% of technology leaders believe their data quality is good enough to scale generative AI. A fabric doesn’t magically fix data quality, but it does give you one governed place to solve it, instead of re-solving it in every project. That’s the core move of the whole pattern: connect each thing once, to the fabric, not many times, to each other.

    Data fabric, AI network fabric, or Microsoft Fabric, which one do you mean?

    Three completely different things wear the word “fabric,” and mixing them up wastes weeks. Here’s the quick map:

    “Fabric”What it actually isWhose problem it is
    Data / software AI fabricAn architecture layer unifying data, models, retrieval, orchestration, and governance in softwareArchitects and ML/data engineers building AI products
    AI network fabricPhysical networking, the interconnect wiring GPUs together (InfiniBand, high-speed Ethernet)Data-center and hardware teams running training clusters
    Microsoft FabricA specific commercial analytics platform from MicrosoftTeams standardized on the Microsoft data stack
    Software data fabric vs AI network fabric — comparison for AI systems

    This guide is about the first one, the architecture you design when you build an AI product. The network fabric is a cabling-and-throughput conversation for whoever runs your GPU cluster, and it barely overlaps with application design. Microsoft Fabric is a real product that happens to share the word; it can serve as part of your data layer, but it isn’t the architectural pattern itself. When someone searches “fabric architecture for AI systems,” they almost always mean the software one. Keep the three straight and half the vendor noise disappears.

    What are the layers of a fabric architecture for AI systems?

    Nearly every production AI system I’ve worked on resolves into the same five layers. You won’t build all five fully on day one, and you shouldn’t try. But naming them tells you what you have, what’s missing, and, most usefully, where the risk is hiding.

    Five-layer fabric architecture for AI systems

    1. The data and knowledge layer. This is the floor everything else stands on: governed access to your structured data, documents, and domain knowledge, usually through connectors, a catalog so people can find what exists, and often a knowledge graph or feature store. When this layer is weak, every layer above inherits the mess, which is why a surprising amount of “AI work” is really data work wearing a costume. In tooling terms this is where things like a warehouse, dbt or Airflow pipelines, and a graph store such as Neo4j tend to live. Getting data into the system cleanly and safely is exactly where careful AI integration pays for itself.

    2. The model and serving layer. Here sit the models, foundation LLMs, small task-specific models, embedding models, anything you fine-tune, plus the serving that turns a model into a fast, affordable endpoint. The piece people skip and later regret is the model gateway: a thin interface every other layer calls, so switching from one provider to another, or routing cheap requests to a small model and hard ones to a big one, doesn’t ripple through your code. Serving stacks like vLLM or a managed endpoint handle the runtime; a registry such as MLflow tracks versions. This is the domain of machine learning development and, when a language model is the product, focused LLM development.

    3. The retrieval and grounding layer. Foundation models don’t know your business and will confidently invent an answer when asked something they don’t know. Retrieval fixes that by fetching the right context, from documents, a database, or the knowledge graph, and handing it to the model at request time. This is where RAG, vector search, chunking, and context assembly live, with vector stores like pgvector, Weaviate, or Pinecone doing the lookup. The mistake is treating it as “just add a vector database.” The accuracy of the entire system is won or lost on retrieval quality: how you chunk, how you rank, how you handle freshness. Solid RAG development is usually the highest-impact work in an enterprise AI build.

    4. The orchestration and agent layer. This is the decision-making: routing a request, planning multi-step work, calling tools and APIs, recovering when a step fails. A simple system retrieves and answers. A serious one plans and acts, which is where real AI agent development, and frameworks like LangGraph, come in. It’s the layer that turns “a bot that talks” into “a system that does work,” and it leans hard on the layer above it for permission before it’s allowed to touch anything that matters.

    5. Governance, security, and observability: the AI fabric security architecture.
    This layer does not sit on top, it wraps the other four, and together they form the AI fabric security architecture. Access control for both users and agents, guardrails and policy, evaluation, plus logging and tracing so you can always answer what the system did and why. In a regulated setting this is not a feature you add later; it is the thing that lets you ship at all. Treat it as part of responsible AI development from the first commit, and use the NIST AI Risk Management Framework as a reference for what governed should mean.

    How is a data fabric different from a data mesh or data lakehouse?

    Short version: a data fabric unifies access through technology and metadata; a data mesh decentralizes ownership to domain teams; a data lakehouse is a storage-and-query platform. They answer different questions and often coexist. This is one of the most-searched confusions in the whole space, so here’s the honest comparison:

    ApproachCore ideaBest when
    Data fabricA unified access layer over distributed data, driven by active metadataYou need consistent, governed access across many systems
    Data meshDecentralized ownership, each domain team owns its data as a productLarge orgs where central data teams are a bottleneck
    Data lakehouseOne platform combining a lake’s flexibility with a warehouse’s structureYou want a single place to store and query all data types

    For an AI fabric, the data-fabric idea is the relevant one, it’s your data-and-knowledge layer. A mesh is an ownership model you might run alongside it; a lakehouse is often the storage the fabric reads from. They’re not competitors so much as answers to “who owns it,” “how do I reach it,” and “where does it sit.” IBM’s own comparison is a good neutral reference if you want to go deeper.

    What does a single request actually look like?

    Abstractions click when you trace one real request through them. Picture a support assistant, and a customer types: “Where’s my order, and can you change the delivery address?”

    The orchestration layer reads that as two intents, a lookup and an action, and plans accordingly. It calls retrieval, which pulls the customer’s order and the delivery policy from the data layer, where access control has already confirmed this agent is allowed to see this customer’s records. The model layer drafts a reply from that grounded context. Because changing an address is a sensitive action, the governance layer forces a checkpoint, a policy check, maybe a human approval, before orchestration is permitted to call the address-change tool. Every hop is logged, so if something looks wrong next week, you can replay exactly what happened.

    Notice what the fabric bought you: the same data access, model gateway, and governance rules that served this request will serve your next ten use cases. You didn’t rebuild grounding or permissioning for the support bot, you reused the fabric. That reuse is the entire economic case for the pattern, and it’s why the second AI feature on a good fabric ships in a fraction of the time the first one did.

    When do you actually need a fabric, and when is it overkill?

    A fabric is an investment that pays back only if you’ll build on it more than once. Over-building it for a single feature is one of the more expensive mistakes I see. So here’s the test I give clients.

    You’re ready for a fabric when:

    • You have, or clearly will have, multiple AI use cases sharing data, models, or infrastructure.
    • Your data is spread across many systems and every project keeps re-solving the same access and governance problems.
    • You need consistent governance and auditing across AI features, non-negotiable in finance, healthcare, or legal.
    • You expect to swap models or vendors and don’t want each change to trigger a rewrite.
    • Several teams build on shared AI foundations and need stable contracts instead of private wiring.

    You should hold off when:

    • You’re shipping one focused feature to learn how users behave.
    • Your data already sits in one or two systems with clean access.
    • You’re pre-product-market-fit and speed beats reuse.

    The sane path for most teams: build the first use case cleanly, keeping the five layers as separate concerns even inside one app, then promote them into a shared fabric as the second and third use cases arrive. You earn the abstraction from real demand instead of guessing at it.

    Should you buy or build your fabric?

    Nobody sells a finished AI fabric in a box, whatever the sales deck says. You assemble one, and the useful rule is: buy the commoditized plumbing, build the parts that encode your domain and your risk.

    • Data layer: mostly buy. Warehouses, catalogs, and vector stores are mature; rebuilding them rarely pays. What stays custom is your domain model and governance rules.
    • Model and serving: buy the models and the runtime; build the thin gateway that gives you routing and cost/latency logging. That small piece of custom code saves outsized pain later.
    • Retrieval: buy the vector database; build the retrieval quality. Chunking, ranking, and freshness are specific to your content, and they decide your accuracy.
    • Orchestration: frameworks accelerate this, but the actual workflows, tool definitions, and failure handling are custom, because they encode how your business runs.
    • Governance and observability: buy the monitoring tools; build the policies, approval flows, and evaluations, because “acceptable behavior” is specific to your risk tolerance.

    Teams that try to build everything drown in undifferentiated infrastructure. Teams that try to buy everything discover the differentiating 20% (retrieval quality, orchestration, governance) was never for sale. Finding that line for your stack is the real substance of serious AI development services, and it deserves a deliberate decision rather than a default.

    Where fabric projects go wrong

    The failure modes are predictable, which is good news, you can design around them.

    The most common is governance as an afterthought: bolting on access control and logging after launch, when it needed to wrap every layer from the start. agentic AI development Retrofitting it into a live agent is painful and sometimes means a rewrite. Close behind is over-engineering, building an elaborate five-layer platform for a single chatbot a weekend prototype could have served. Then there’s the gap between a demo and production: a prototype that works once in a clean test is not a system that holds up against real data, adversarial users, and edge cases, and that gap lives almost entirely in retrieval quality, evaluation, and guardrails rather than in model choice.

    Two more worth calling out. Skipping evaluation means every “improvement” is a guess, because you can’t tell whether a change made the system better or worse. And chasing the model instead of the system, spending weeks debating which LLM to use while the retrieval and orchestration layers, which matter far more to the result, get thrown together. Avoiding all of these is less about adding technology and more about sequencing: govern early, abstract only what you’ve proven you need, measure everything.

    How do you adopt a fabric without over-building?

    You grow a fabric; you don’t build it in one heroic project. A sane sequence looks like this.

    Start with one high-value, manageable-risk use case, a grounded internal assistant, a support deflector, one automation. Build it cleanly, but keep the five layers as distinct concerns even inside that single app rather than one tangled script. When the second use case arrives, you’ll notice you’re re-implementing data access or model calls; that’s your signal to promote those into shared services, a real model gateway, a shared retrieval service, a common policy. Now you’re factoring out what you’ve proven is common, not what you guessed would be.

    Most teams land on one of three fabric configurations: centralized, federated, or hybrid, and the right one depends on how your data and risk are spread.

    Make governance and observability a first-class shared layer as soon as more than one use case exists, or the moment any agent can take a consequential action. This is the one place worth investing slightly ahead of need, because it’s the most expensive thing to retrofit. After that, scale is the reward: each new use case inherits the fabric instead of rebuilding it, and the cost curve bends in your favor.

    Key takeaways

    • A fabric architecture for AI systems is a shared software layer connecting data, models, retrieval, orchestration, and governance so they behave as one system.
    • It exists to kill the point-to-point integration tangle: connect each thing once to the fabric, not many times to each other.
    • Three different things are called “fabric”, the software/data fabric (your concern), the AI network fabric (GPU hardware), and Microsoft Fabric (a product). Don’t conflate them.
    • Think in five layers: data & knowledge, model & serving, retrieval & grounding, orchestration & agents, and cross-cutting governance & observability.
    • Buy the plumbing, build what encodes your domain and risk, retrieval quality, orchestration, and governance.
    • Earn the abstraction: ship one clean use case first, then formalize the fabric as more arrive. Govern early, measure everything.

    Frequently asked questions

    What is a fabric architecture for AI systems?

    A fabric architecture for AI systems is a shared software layer that connects data, models, retrieval, orchestration, and governance through consistent interfaces, so the parts work as one coordinated system instead of many brittle point-to-point integrations. You connect each component to the fabric once, rather than wiring every component directly to every other one.

    What is the difference between a data fabric and a data mesh?

    A data fabric is a technical layer that unifies access to distributed data using metadata and automation. A data mesh is an organizational model that gives each domain team ownership of its data as a product. One is about how you reach the data; the other is about who owns it. Many large organizations run both together.

    Is a data fabric the same as a data lake or data warehouse?

    No. A data lake or warehouse is where data is stored; a data fabric is a layer that provides unified, governed access across those stores and other sources. A fabric often reads from a lake, lakehouse, or warehouse rather than replacing it, so the two work together instead of competing.

    What is the difference between an AI fabric and Microsoft Fabric?

    An AI fabric is a general architecture pattern for connecting the layers of an AI system. Microsoft Fabric is a specific commercial analytics platform from Microsoft. Microsoft Fabric can serve as part of your data layer, but it is a product you buy, not the architectural pattern itself. The two are easy to confuse but different.

    Is an AI fabric just RAG?

    No. RAG, or retrieval augmented generation, is one layer of a fabric, the retrieval and grounding layer. A full AI fabric also includes the data layer, model serving, orchestration and agents, and cross-cutting governance. RAG makes individual answers accurate; the fabric makes the whole system reusable, governed, and cheap to extend.

    Is a fabric hardware or software?

    It depends which fabric you mean. A software or data AI fabric is an architecture you design in code and configuration. An AI network fabric is physical networking hardware that connects GPUs inside a data center. This guide is about the software architecture, which is what most people mean when they are building AI products.

    Do I need a fabric architecture for a single AI feature?

    Usually not. A single grounded chatbot or one automation can ship cleanly without a full fabric. A fabric earns its cost once you have multiple AI use cases sharing data, models, and governance. Build the first feature cleanly, keep the layers as separate concerns, then formalize a fabric as more use cases arrive.

    How do you keep a fabric architecture secure and governed?

    Treat governance as a layer that wraps every other layer from day one: access control for both users and agents, guardrails and content policy, evaluation and testing, plus logging and tracing so every action is auditable. The NIST AI Risk Management Framework is a useful reference for what a governed system should include.

    What are the layers of a fabric architecture for AI systems?

    Most production systems resolve into five layers: a data and knowledge layer for governed access, a model and serving layer with a gateway, a retrieval and grounding layer for RAG, an orchestration and agent layer for planning and actions, and a governance and observability layer that wraps the other four.

    How much does it cost to build a fabric architecture?

    There is no fixed price, because you assemble a fabric from tools rather than buying one product. Most of your budget goes to the custom parts that encode your domain: retrieval quality, orchestration, and governance. The commoditized plumbing, such as warehouses and vector stores, is bought, so cost scales with how many use cases you support.

    How long does it take to implement a fabric architecture?

    You do not build a whole fabric at once. A first grounded use case with clean separation of the five layers typically takes a few months. The fabric itself emerges as you promote shared services, like a model gateway or a common retrieval service, once a second and third use case prove what is worth reusing.

    Should you buy or build a fabric architecture?

    Both. The rule is to buy the commoditized plumbing and build the parts that encode your domain and risk. Buy warehouses, vector stores, models, and monitoring. Build the thin model gateway, your retrieval quality, the orchestration workflows, and your governance policies. Teams that try to build everything drown; teams that buy everything lose their edge.

    Do I need a consultant or partner to build an AI fabric?

    Not always, but a partner helps most where the decisions are hard to reverse: designing the five layers, choosing what to buy versus build, and getting governance right from the start. Many teams build the first use case in-house, then bring in specialists to formalize the shared fabric as more use cases arrive.

    Is a fabric architecture worth it for a startup or small business?

    Often not yet. If you are shipping one focused feature or your data sits in one or two systems, a full fabric is premature and speed matters more than reuse. Build the first use case cleanly with the layers as separate concerns, then earn the fabric once you have several AI features to share.

    Can a fabric architecture integrate with our existing tools and data?

    Yes, and that is much of the point. A fabric connects to your existing warehouses, databases, document stores, and APIs through connectors, then presents them behind consistent interfaces. You connect each system to the fabric once, so new AI use cases reuse that governed access instead of every project building its own integration to every source.

    How does a fabric architecture handle real-time data?

    Through the data and knowledge layer, which can serve live streams and fresh sources alongside stored data, and through retrieval that fetches current context at request time. Freshness is a design decision in how you chunk, index, and refresh, so real-time behavior comes from the retrieval and data layers rather than from the model.

    What skills does my team need to build a fabric architecture?

    A fabric spans several disciplines: data engineering for the access layer, ML and LLM engineering for models and serving, retrieval and RAG expertise for grounding, and software and DevOps skills for orchestration, security, and observability. You rarely need all of it in-house at once. Start with the layers your first use case actually touches.

    What is AI fabric?

    An AI fabric is the software version of a fabric architecture applied end to end: it connects your data, models, retrieval, orchestration, and governance into one governed layer, so AI moves from isolated features to a coordinated system. It is the same five-layer pattern this guide describes, named for the whole stack rather than any single layer.

    The bottom line

    Fabric architectures for AI systems aren’t a product to buy or a buzzword to chase. They’re a way of treating AI as a system of interchangeable, governed parts instead of a pile of one-off integrations, and the payoff is that your second use case, and your tenth, get dramatically cheaper to build. If you’re mapping how these layers should fit your stack, that’s the architecture work we do every day; reach out at hello@mobilions.com or explore our AI development services.
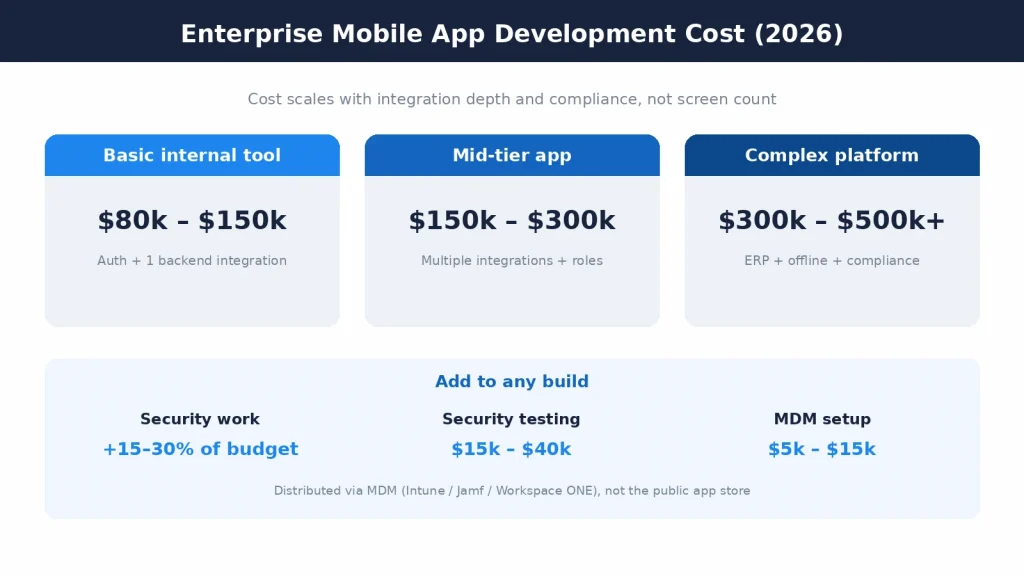
  • Enterprise Mobile App Development: The Complete 2026 Guide

    Enterprise Mobile App Development: The Complete 2026 Guide

    Enterprise mobile app development is what happens when a mobile app has to answer to an IT department, a security team, and a compliance auditor, not just an app store reviewer. It is a different discipline from building a consumer app, and treating the two the same is the fastest way to blow a budget and a deadline.

    This guide explains what makes enterprise mobile app development different, how the build actually works, what the stack looks like in 2026, how apps get distributed through MDM instead of public stores, and what all of it costs. It is written from the perspective of engineers who scope, build, and support these systems in production.

    What is enterprise mobile app development?

    Enterprise mobile app development is the process of building mobile applications for internal business use, such as field operations, logistics, sales enablement, or employee tools, that must integrate with existing company systems and meet strict security and compliance requirements.

    The users are employees, partners, or vetted customers, not the open public. That single fact changes almost everything: how the app authenticates people, where it gets its data, how it is distributed, and how it is governed after launch.

    A consumer app optimizes for downloads and delight. An enterprise app optimizes for reliability, security, and fit with the systems a business already runs. Both are mobile apps. Only one has to pass a SOC 2 audit.

    Why enterprise mobile apps are different from consumer apps

    The gap shows up in four places, and each one adds cost and engineering care that a consumer app never sees.

    Security is a first-class requirement, not a feature. Enterprise mobile apps carry role-based access control, single sign-on through SSO or LDAP, encrypted local storage, and often certificate pinning. Security work typically adds 15 to 30 percent to a development budget, and that is money well spent rather than overhead.

    They integrate with legacy systems. An enterprise app rarely stands alone. It has to talk to an ERP, a CRM, a data warehouse, or a decades-old internal API that was never designed for mobile. This integration depth, not the number of screens, is usually the biggest driver of cost and timeline.

    They are governed after launch. Consumer apps ship and iterate freely. Enterprise apps live under IT policy: managed updates, remote wipe, device compliance checks, and audit trails. The app has to cooperate with that governance from day one.

    They run at organizational scale with offline realities. Warehouse floors, hospital basements, and remote sites have poor connectivity, so offline mode and reliable sync are common requirements rather than nice-to-haves.

    Enterprise mobile application development services: what you actually get

    When you hire a team for enterprise mobile application development, the deliverable is not just an app binary. It is a system that IT can trust and operate.

    A complete service covers discovery and security scoping, UX for real workflows rather than marketing screens, the mobile app itself, the backend and integration layer, and the deployment and support model. The integration layer, connecting the app to your ERP, CRM, identity provider, and data systems, is often where most of the real engineering lives.

    Good enterprise mobile app development services also include the unglamorous parts: role and permission modeling, audit logging, compliance documentation, and a rollout plan. These are the things that decide whether the app is adopted or abandoned.

    The point of naming this clearly is simple. If a vendor quotes you only for screens and features, they have not scoped the enterprise part of enterprise mobile app development, and the number will move once reality arrives.

    How to build enterprise mobile apps: the process

    Knowing how to build enterprise mobile apps is mostly about doing the hard thinking before writing code. The process we use runs in five stages.

    Discovery and security scoping. Map the workflows, the systems the app must integrate with, the compliance regime (HIPAA, SOC 2, ISO 27001, GDPR), and the device and distribution model. This is where the true scope, and the honest cost, becomes visible.

    Architecture. Decide the integration approach, the offline and sync strategy, the identity model (SSO, LDAP, OAuth), and the platform choice. Cross-platform frameworks like Flutter and React Native are common here because they cut the cost of shipping to both iOS and Android.

    Development. Build the app, the backend, and the integration layer in parallel, with security controls baked in rather than bolted on. Role-based access, encrypted storage, and audit logging are written as the app is written.

    Security testing and hardening. Enterprise apps get a dedicated security pass, penetration testing, and a hardening phase. Budget roughly 4 to 8 weeks and $15,000 to $40,000 for thorough enterprise security testing on a serious app.

    Deployment and support. Package the app for MDM distribution, plan the rollout, train users, and stand up ongoing support. The launch is the start of the app’s life, not the end of the project.

    One detail that separates an enterprise build from a consumer app is identity and device control. Enterprise apps usually need single sign-on through the company’s existing identity provider, role-based permissions, audit logging, and mobile device management so IT can push updates and wipe a lost device. Building this in from the start is far cheaper than adding it after launch, and it is often exactly what a low quote leaves out.

    The technology stack for enterprise mobile apps

    There is no single correct stack, but enterprise choices cluster around a few sensible defaults in 2026.

    On the client, cross-platform frameworks (Flutter, React Native) dominate internal apps because one codebase serving iOS and Android roughly halves the build and maintenance cost. Native (Swift, Kotlin) is chosen when the app needs deep device features or maximum performance.

    On the backend, teams reach for well-supported, boring-in-a-good-way choices: Node.js, Python, Java, or Go, with PostgreSQL or a managed cloud database, running on AWS, Azure, or Google Cloud. The premium is on reliability and support, not novelty.

    For identity and security, the stack includes an enterprise identity provider (Okta, Microsoft Entra, or the company’s existing directory), SSO and LDAP integration, and mobile security controls aligned to the OWASP Mobile Application Security standard. Our mobile app development and custom software development teams treat this integration middleware, which connects the app to the ERP and CRM systems the business already runs, as the core of the build.

    Enterprise mobile app distribution and MDM deployment

    Here is the difference that surprises teams new to this: enterprise apps usually do not ship through the public App Store or Google Play. They are distributed privately through Mobile Device Management.

    How enterprise mobile apps are deployed through MDM by Mobilions

    Enterprise mobile app distribution runs through MDM platforms such as Microsoft Intune, VMware Workspace ONE, or Jamf, paired with Apple Business Manager and Android Enterprise. The app is pushed to managed devices, configured by policy, and updated centrally, with the ability to remotely wipe it if a device is lost.

    This MDM enterprise app deployment model is what lets IT enforce compliance: only enrolled, policy-compliant devices get the app, and access can be revoked instantly. It also means your enterprise mobile app development platform choices have to be MDM-compatible from the start, because retrofitting management support later is painful.

    Practically, MDM integration and setup adds roughly $5,000 to $15,000 to a project, depending on the platform and how many device types need management policies. That is a small line item next to the adoption and security it buys.

    How much does enterprise mobile app development cost in 2026?

    Cost scales with compliance burden and integration depth far more than with screen count. With that framing, 2026 numbers fall into three honest bands.

    Enterprise mobile app development cost bands for 2026 by Mobilions

    A basic internal tool, with authentication and a single backend integration, runs about $80,000 to $150,000. A mid-tier app, with multiple integrations and user roles, runs about $150,000 to $300,000. A complex platform, with ERP integration, offline mode, and formal compliance, runs $300,000 to $500,000 and can pass $1,000,000 for the largest programs.

    Inside those totals, security work adds 15 to 30 percent, dedicated security testing adds $15,000 to $40,000, and MDM setup adds $5,000 to $15,000. None of these are places to cut, because they are the parts that make the app safe to deploy across an organization.

    The most useful thing you can do for your budget is scope the integrations and compliance early. That is where enterprise mobile app development costs are made or blown, and a vendor who scopes them honestly will save you far more than one who quotes a low number and discovers the ERP later.

    Build versus buy: when a custom enterprise app makes sense

    Not every internal need justifies a custom build, and an honest enterprise mobile app development partner will tell you when to buy instead.

    Off-the-shelf software wins when your process is standard and a mature product already fits it, such as generic expense tracking or standard field-service ticketing. You get it faster and cheaper, and someone else maintains it. Forcing a custom build on a solved problem is a waste of budget.

    Custom enterprise mobile app development wins when the workflow is your competitive edge, when integration with your specific systems is deep, or when compliance and data control rule out a shared SaaS product. If the app has to bend to your ERP and your rules rather than the other way around, buying rarely works.

    The middle path is common: buy the commodity pieces and build the parts that are truly yours, connected through an integration layer. The decision should come from the workflow and the integration depth, not from a preference for building. Scope it honestly and the answer is usually clear before a line of code is written.

    Choosing an enterprise mobile app development company

    The right enterprise mobile app development company is one that talks about your systems and your security before it talks about screens. That is the fastest signal of whether they have done this before.

    Look for real integration experience with ERP, CRM, and identity systems, a documented security and compliance track record, and a support model that lasts beyond launch. Ask how they handle MDM distribution and managed updates, because a team that has shipped enterprise apps will have a clear answer. If you need to scale a team quickly, you can also hire mobile developers who already work this way.

    Be cautious of quotes that price only the visible app. A serious enterprise mobile application development company scopes the integration layer, the security work, and the rollout, and it will tell you when your requirements push the project into a higher cost band rather than discovering it mid-build.

    Ownership matters too. You should own the code, the infrastructure, and the roadmap. A good partner builds the app to hand it over, not to lock you in.

    A quick example: what an enterprise build looks like in practice

    Consider a logistics company that wants a driver and warehouse app. It needs to work offline in low-signal areas, sync when connectivity returns, read and write to the existing ERP, authenticate staff through the company’s identity provider, and deploy to company-owned devices only.

    The scope decisions follow directly. Cross-platform on Flutter to cover both device types cheaply. An integration layer between the app and the ERP so the app never talks to the ERP directly. Offline-first data with conflict-safe sync. SSO through the existing directory, role-based access for drivers versus supervisors, and audit logging for compliance.

    Distribution goes through Intune, not the public store, so IT controls who has the app and can wipe a lost device. On these requirements the project lands in the mid-to-complex band, and the integration and offline work, not the screen count, is what sets the price.

    Notice what drove every decision above: not the number of screens, but the systems the app had to touch and the environment it had to survive. Change the ERP or the connectivity and the estimate changes with it. That is enterprise mobile app development in one concrete picture, and it is why honest scoping beats a low quote every time.

    Core features that define enterprise mobile applications

    Certain capabilities show up in almost every serious build, and together they are what separate enterprise mobile applications from ordinary apps. Knowing them helps you scope realistically and judge a vendor’s quote.

    Role-based access control comes first. Different employees see and do different things, so the app models roles and permissions rather than treating every user the same. This alone touches the UI, the backend, and the audit layer.

    Single sign-on is expected, not optional. Employees should sign in with the same identity they use for everything else, through SSO, LDAP, or OAuth against the company directory, so there is no separate password to manage or leak.

    System integration is usually the heart of the app. Enterprise apps read and write to ERP, CRM, and data platforms, and that integration layer is where most of the engineering time goes. Offline mode and reliable sync sit alongside it, because real work happens in places with poor connectivity.

    Finally, audit logging, encrypted storage, and MDM compatibility round out the baseline. These are the controls that let a security team sign off and an auditor tick the box, and they are the reason enterprise mobile app development is scoped differently from a consumer build.

    Compliance and industry considerations

    The compliance regime an app falls under changes the scope more than almost any feature decision, so it belongs in the first conversation, not the last.

    In fintech, enterprise mobile app development carries PCI DSS obligations, strong authentication, transaction integrity, and audit trails, and the security bar is high because the data is money. Anything touching payments or account data is scoped as sensitive from the start.

    In healthcare, HIPAA governs how patient data is stored, transmitted, and accessed, which pushes encryption, access logging, and strict role controls to the front. An app that handles protected health information is a compliance project with a mobile front end, not a mobile project with a compliance checkbox.

    In logistics and field operations, the pressure is less about regulation and more about reliability: offline-first behavior, device durability, and clean ERP sync. Different industries stress different parts of the same discipline, which is why a team that has shipped in your sector scopes faster and more honestly.

    The common thread is that compliance and integration depth, taken together, set the true size of an enterprise build. A vendor who asks about your regulatory environment early is protecting your budget, not padding it.

    Common mistakes that derail enterprise mobile app projects

    Most enterprise mobile app development trouble is predictable, and nearly all of it traces back to scoping the wrong things.

    The first mistake is pricing screens instead of integrations. The visible app is the cheap part; the ERP, CRM, and identity connections are where the effort lives. A quote that ignores them will be wrong, and the correction always arrives mid-build when it is most expensive.

    The second is treating security and compliance as a final phase. Retrofitting encryption, role-based access, and audit logging into a finished app costs far more than building them in, and it often forces a redesign. Security scoped late is security done twice.

    The third is ignoring distribution until the end. If the app was not built to be MDM-compatible, packaging it for managed deployment becomes its own mini-project. Distribution is an architecture decision, not a launch-day task.

    The fourth is skipping the rollout and training plan. An enterprise app that nobody adopts is a total loss regardless of how well it is built, and adoption depends on a real rollout, not a launch email. The engineering is only half the job; getting the app onto devices and into daily use is the other half.

    Frequently asked questions

    What is enterprise mobile app development?

    Enterprise mobile app development is building mobile apps for internal business use that integrate with company systems like ERP and CRM, enforce enterprise security and access controls, and meet compliance requirements. The users are employees or vetted partners rather than the general public.

    How to build enterprise mobile apps?

    Choose a company that scopes your integrations, security, and rollout before pricing screens, has real ERP, CRM, and identity integration experience, documents its security and compliance work, offers support beyond launch, and hands you full ownership of the code and infrastructure.

    How much does enterprise mobile app development cost in 2026?

    A basic internal tool costs about $80,000 to $150,000, a mid-tier app with multiple integrations and roles about $150,000 to $300,000, and a complex platform with ERP integration, offline mode, and compliance $300,000 to $500,000 or more. Security adds 15 to 30 percent and MDM setup adds $5,000 to $15,000.

    How long does it take to build an enterprise mobile app?

    A basic internal tool can take a few months; a mid-tier app with several integrations typically runs four to eight months; a complex compliant platform can run eight months or more. Security testing alone adds roughly four to eight weeks.

    How do we choose an enterprise mobile app development company?

    How do we choose an enterprise mobile app development company?

    Why are enterprise mobile apps more expensive than consumer apps?

    Because cost scales with compliance and integration depth, not screen count. Enterprise apps must connect to legacy systems, enforce role-based security and SSO, support offline use, pass security testing, and deploy under IT governance, all of which a consumer app skips.

    What is MDM enterprise app deployment?

    MDM (Mobile Device Management) enterprise app deployment distributes an app privately to managed devices through platforms like Microsoft Intune, VMware Workspace ONE, or Jamf, rather than the public app stores. It lets IT enforce device compliance, push updates centrally, and remotely wipe the app if a device is lost.

    Should we build native or cross-platform for an enterprise app?

    Cross-platform frameworks like Flutter and React Native are the common default for internal enterprise apps because one codebase for iOS and Android roughly halves build and maintenance cost. Native is worth it when the app needs deep device features or maximum performance.

    Build an enterprise app that IT will actually trust

    Enterprise mobile app development succeeds or fails on the parts users never see: the integrations, the security, and the deployment. If you are scoping an internal app and want an honest read on cost, timeline, and stack, talk to Mobilions. Senior engineers scope it, build it, ship it through your MDM, and support it in production.

  • Fitness Mobile App Development: A Complete 2026 Guide

    Fitness Mobile App Development: A Complete 2026 Guide

    Fitness mobile app development in 2026 costs roughly $25,000 to $40,000 for a lean MVP, $70,000 to $110,000 for a solid cross-platform app (about 12 to 16 weeks), and $120,000 to $300,000+ for a feature-rich, multi-platform product. Wearable sync with Apple Health, Google Fit, Fitbit, and Garmin is now expected, not optional. The smart path for most founders is a cross-platform MVP with five to seven core features, validate real usage and retention, then invest further. The market is large (around $13.5 billion in 2026 and growing about 13 percent a year), but most apps fail on retention, so build for the second week, not just the first download.

    Fitness app development looks simple from the outside, a few workout screens and a timer, and expensive and confusing the moment you actually start pricing it. The truth sits in between. A fitness app is a real software product with wearable integrations, health data, subscriptions, and a brutal retention problem, and what you build and how you build it decides whether it earns money or joins the graveyard of abandoned fitness apps.

    This guide is the practical version for founders and fitness businesses. It covers what fitness mobile app development actually involves in 2026, whether the market is worth entering, the features users expect, real cost and timeline ranges, the native-versus-cross-platform decision, monetization, why apps fail, and how to choose a development team. We build mobile apps at Mobilions, so this is a builder’s view with real numbers, not a sales pitch dressed as a guide.

    What fitness mobile app development actually involves in 2026

    It helps to see the whole scope before the price tags, because the cost follows directly from it. A modern fitness app is several systems working together.

    There is the app itself on iOS and Android, the workout and content engine (plans, exercises, timers, tracking), wearable and health integrations so the app reads steps, heart rate, and workouts from the devices people already wear, a backend for accounts, data, and sync, subscriptions and payments, and the analytics you need to understand retention. On top of that sit the parts founders often forget: onboarding, notifications, a content pipeline to keep workouts fresh, and ongoing maintenance after launch.

    The reason fitness apps cost more than a simple utility is this integration surface. Reading health data correctly, syncing across devices, and keeping subscriptions and content flowing is where the engineering hours go, and it is also what separates an app people keep from one they delete in a week.

    Is a fitness app worth building? The 2026 market

    Before spending anything, it is fair to ask whether the market justifies it, and the numbers are encouraging with a catch.

    The fitness app market is large and growing, roughly $13.5 billion in 2026 and projected to keep expanding at about 13 percent a year, according to market research. Health and fitness apps also monetize better than most categories: subscriptions drive the majority of revenue, most of it from annual plans, and the category has one of the highest lifetime values on the App Store. Wearable-connected fitness is the fastest-growing slice as more people own a Fitbit, Garmin, or smartwatch.

    The catch is that a big market is also a crowded one, and averages hide a harsh distribution: a small number of apps take most of the money while the majority struggle to retain users. So the honest answer to “is it worth it” is yes, the market is real and monetizable, but only if your app earns its place through genuine value and retention. Building one because the market is big, without a reason users would stay, is how you become part of the losing majority.

    Features users actually expect

    Feature scope is the single biggest driver of cost, so it pays to separate what is essential from what is nice to have.

    Fitness app features 2026: core, expected, and differentiator features to prioritise

    Core, non-negotiable features: account and profile, workout plans and exercise library, activity and progress tracking, and clean onboarding. Expected in 2026, not optional: wearable and health-app sync (Apple Health via Apple’s HealthKit, Google’s Health Connect, plus Fitbit and Garmin), push notifications and reminders, and subscription payments. Differentiators worth considering: AI-assisted plans or coaching, social and community features, live or on-demand classes, nutrition and macro tracking, and gamification. Often overlooked but important: solid analytics, a content management system so you can update workouts without a new release, and accessibility.

    The mistake is trying to ship all of it at once. The features that matter most for launch are the core set plus wearable sync and a reason to come back; everything else can follow once real users tell you what they want.

    How much does fitness mobile app development cost?

    Here are honest 2026 ranges. Your number depends on features, platforms, team location, and design polish, but these brackets are realistic.

    Fitness mobile app development cost 2026: MVP, cross-platform, and feature-rich price and timeline tiers

    A lean MVP with five to seven core features runs about $25,000 to $40,000. A solid cross-platform app with tracking, wearable sync, and subscriptions typically lands $70,000 to $110,000 over roughly 12 to 16 weeks. Add templated workout plans, macro tracking, barcode scanning, and richer content and you are looking at $120,000 to $190,000 over five to seven months. A feature-rich, multi-platform product with AI, live classes, and heavy custom design can reach $300,000 or more.

    Then there are the costs founders miss: ongoing maintenance (budget roughly 15 to 20 percent of build cost per year), backend and hosting, third-party services (payments, analytics, push), app store fees, and content creation to keep the app fresh. An app is not a one-time purchase; it is a product you fund over its life. Planning only for the build and not the year after it is the most common budgeting mistake.

    How long does it take?

    Timeline tracks scope closely, so use these as planning anchors.

    A basic MVP typically takes 8 to 12 weeks. A full-featured cross-platform app runs 4 to 7 months. A large, multi-platform product with AI and custom everything can take longer still. Those windows assume a focused scope and prompt decisions from your side; the fastest way to blow a timeline is to keep changing the requirements mid-build. A good team will push you to lock an MVP scope precisely so you can launch, learn, and then expand, rather than chasing a perfect first version that never ships.

    Native vs cross-platform: the real decision

    This choice shapes both cost and quality, so it deserves a clear-eyed look rather than a religious one.

    Native (Swift for iOS, Kotlin for Android) gives the best possible performance and the tightest access to device and health features, at a cost: you build two apps, which roughly doubles the effort and price. Cross-platform (Flutter or React Native) builds one codebase for both platforms, cutting time and cost substantially while delivering performance that is more than good enough for the vast majority of fitness apps. For most founders in 2026, cross-platform is the sensible default, especially for an MVP, because it gets you to both stores faster and cheaper.

    The pragmatic pattern many teams use: start with a cross-platform MVP to validate demand, then, if and when you have real traction and a specific need for native performance, invest in native for the platform that matters most. Choosing native from day one for a product you have not validated is how budgets disappear before you have a single retained user.

    iOS, Android, or both?

    A related question, with a simple framing. If budget is tight and you want to validate, launch on both at once via cross-platform, which a single Flutter or React Native build gives you almost for free compared with two native apps. If you must pick one to start, choose the platform where your audience actually is: iOS users tend to spend more on subscriptions, while Android has larger global reach, so the right answer depends on your market, not on a general rule. For most consumer fitness apps targeting the US and similar markets, launching on both through cross-platform is the cleanest path.

    Build custom or use a template?

    Templates and app builders exist, and they have a place, so here is the honest trade-off.

    A template or no-code builder can get a very simple fitness app live cheaply and fast, which is fine for a basic idea you want to test with minimal money. The limits show up quickly: templates struggle with deep wearable integration, custom workout logic, real scalability, and the polish that retention depends on, and you do not own the foundation. A custom build (or a custom MVP) costs more but gives you the integrations, the experience, and the ownership that a real product needs. A reasonable rule: use a template only to test a concept with near-zero budget; build custom the moment you are serious about retention and growth.

    How to monetize a fitness app

    Revenue model matters as much as features, and the data points clearly in one direction.

    Subscriptions are the dominant and most durable model for fitness apps, with annual plans driving most of that revenue, so a freemium-to-subscription funnel (free core, paid premium plans, coaching, or content) is the default worth designing around. Other models include one-time purchases or unlocks, in-app purchases for specific content, ads (usually weak for fitness and often at odds with a premium feel), and B2B2C deals with gyms, employers, or insurers. For most consumer fitness apps, a well-designed subscription with a genuine free tier and clear premium value is the model to build for, and it should be designed in from the start, not bolted on later.

    Why fitness apps fail (and how to avoid it)

    Most fitness apps do not fail on features; they fail on retention, so this is where to focus.

    The common pattern is a strong first download and a collapse by week two, because the app gave people no reason to come back or asked too much too soon. The fixes are consistent: nail onboarding so users reach value fast, use notifications and streaks thoughtfully to build habit without nagging, sync with wearables so tracking is effortless, keep content fresh so there is always a reason to open the app, and measure retention obsessively from day one. Building for the first install instead of the second week is the single most expensive mistake in this category, and it is entirely avoidable with the right priorities.

    How to choose a fitness app development company

    Since the team you pick largely determines the outcome, evaluate it properly.

    Look for a partner with real mobile and health-integration experience (ask to see fitness or health apps they have shipped), a clear MVP-first process rather than a push to build everything at once, transparent pricing with no vague lump sums, and honest answers about trade-offs, cost, and timeline. Ask what is included (design, backend, testing, store submission, post-launch support), who owns the code (you should), and how they handle maintenance. Watch for red flags: prices that seem too good to be true, no relevant portfolio, reluctance to explain the plan, or promises to build a huge app cheaply and fast. The right questions up front save far more than they cost.

    How Mobilions helps

    We build fitness and health mobile apps end to end, and we have shipped software since 2016. For founders, we start with a tight MVP: the core features plus wearable sync and the retention basics, built cross-platform so you reach both stores fast and affordably, with a clear path to native later if your traction justifies it. We handle the hard parts properly, Apple Health and Google Fit integration, subscriptions, sync, and analytics, design for the second-week return rather than just the first download, and hand you full ownership of the code. We are also honest when a smaller build or a phased plan serves you better than the biggest version.

    What we will not do is sell you a $300,000 app when a $40,000 MVP is what you need to validate the idea, because the point is a product that earns its keep, not the largest possible invoice.

    The bottom line

    Fitness mobile app development in 2026 is a real investment with real returns for the apps that earn retention. Budget roughly $25,000 to $40,000 for an MVP, $70,000 to $110,000 for a solid cross-platform app, and more for a feature-rich product, and remember the ongoing costs after launch. Expect wearable sync as standard, build cross-platform first for most cases, and design subscriptions and retention in from the start.

    The market is large and monetizes well, but it is crowded and unforgiving, and most apps fail on the second week rather than the first. Start focused, validate with a real MVP, measure retention, and expand from evidence rather than ambition. Do that, and a fitness app is one of the better products you can build in 2026. Rush a bloated first version without a retention plan, and it will be one of the more expensive lessons.

    If you want a straight estimate and an MVP plan for your specific fitness app idea, that is exactly the conversation our senior mobile engineers have with founders every week.

    Book a discovery call for an honest scope and quote, no obligation. You can also explore our mobile app development services and how we work with fitness and wellness businesses.

    Key takeaways

    • Fitness mobile app development in 2026 costs about $25,000 to $40,000 for an MVP, $70,000 to $110,000 for a solid cross-platform app, and $120,000 to $300,000+ for feature-rich, multi-platform products.
    • Wearable and health-app sync (Apple Health, Google Fit, Fitbit, Garmin) is now expected, not a premium add-on.
    • Timelines run about 8 to 12 weeks for an MVP and 4 to 7 months for a full app; changing scope mid-build is the main cause of delays.
    • Cross-platform (Flutter or React Native) is the sensible default for most apps and MVPs; go native later if traction and performance needs justify it.
    • Budget for ongoing costs (maintenance about 15 to 20 percent of build per year, hosting, content, store and service fees), not just the build.
    • Subscriptions, especially annual plans, are the dominant and most durable monetization model; design the funnel in from the start.
    • Most fitness apps fail on retention, not features; nail onboarding, wearables, fresh content, and second-week return, and choose a team with real health-app experience.

    Frequently asked questions

    How much does it cost to build a fitness app in 2026?

    A lean MVP with five to seven core features costs about $25,000 to $40,000. A solid cross-platform app with tracking, wearable sync, and subscriptions typically runs $70,000 to $110,000, and a feature-rich, multi-platform product can reach $120,000 to $300,000 or more. The final number depends on features, platforms, team location, and design, and you should also budget ongoing costs of roughly 15 to 20 percent of the build per year.

    How long does it take to develop a fitness app?

    A basic MVP usually takes 8 to 12 weeks, and a full-featured cross-platform app takes 4 to 7 months. Larger products with AI, live classes, and custom design take longer. These timelines assume a focused, locked scope, changing requirements mid-build is the most common cause of delays, so agreeing a precise MVP scope up front is the fastest route to launch.

    Should I build my fitness app native or cross-platform?

    For most founders, cross-platform (Flutter or React Native) is the sensible default, especially for an MVP, because it builds one codebase for both iOS and Android, cutting time and cost while delivering more than enough performance for a fitness app. Native (Swift and Kotlin) gives the best performance and device access but roughly doubles the cost. A common pattern is a cross-platform MVP first, then native later if traction justifies it.

    iOS, Android, or both, which should I launch on?

    If you build cross-platform, you can launch on both at once for close to the cost of one, which is usually the best path for validation. If you must pick one, choose where your audience is: iOS users tend to spend more on subscriptions, while Android has larger global reach. For most US-focused consumer fitness apps, launching on both through a cross-platform build is the cleanest option.

    What features should a fitness app have?

    The core essentials are accounts, workout plans and an exercise library, progress tracking, and clean onboarding. In 2026, wearable and health-app sync, notifications, and subscription payments are expected too. Differentiators like AI coaching, social features, live classes, and nutrition tracking are worth adding once the core proves itself. Avoid shipping everything at once, launch with the essentials plus a strong reason to return.

    Is a fitness app a good investment?

    The market is large, around $13.5 billion in 2026 and growing about 13 percent a year, and fitness apps monetize better than most categories, mainly through subscriptions. But it is crowded, and most apps fail on retention, so it is a good investment only if your app delivers genuine, repeatable value that keeps users coming back. Validate with an MVP and measure retention before investing heavily.

    Why do so many fitness apps fail?

    Most fail on retention rather than features: a strong first download followed by a collapse in week two, because the app gave users no reason to return or demanded too much too soon. The fixes are fast onboarding, thoughtful notifications and streaks, effortless wearable-based tracking, fresh content, and measuring retention from day one. Building for the first install instead of the second week is the category’s most expensive mistake.

    How should I monetize my fitness app?

    Subscriptions are the dominant and most durable model, with annual plans driving most revenue, so a freemium-to-subscription funnel (free core plus paid premium content or coaching) is the default to design around. Other options include in-app purchases, one-time unlocks, ads (usually weak for fitness), and B2B2C deals with gyms or employers. Design the subscription and its free-tier value from the start rather than adding it later.

    Can I use a template or app builder for a fitness app?

    A template or no-code builder can launch a very simple app cheaply, which is fine for testing a basic idea with minimal budget. But templates struggle with deep wearable integration, custom logic, scalability, and the polish retention needs, and you do not own the foundation. Use a template only to test a concept with near-zero budget, and build custom once you are serious about retention and growth.

    How do I choose a fitness app development company?

    Look for real mobile and health-integration experience (ask to see shipped fitness or health apps), an MVP-first process, transparent pricing, and honest answers about trade-offs. Confirm what is included, who owns the code (you should), and how maintenance works. Watch for red flags like prices that seem too good to be true, no relevant portfolio, or promises to build a huge app cheaply and fast.

    Does Mobilions build fitness mobile apps?

    Yes. We build fitness and health apps end to end, starting with a focused cross-platform MVP, core features plus wearable sync and retention basics, with a clear path to native later. We handle Apple Health and Google Fit integration, subscriptions, sync, and analytics, design for the second-week return, and hand you full ownership. Book a discovery call for an honest scope, timeline, and quote for your idea.

  • AI Agent Enterprise Data Security and Compliance: A Complete 2026 Guide

    AI Agent Enterprise Data Security and Compliance: A Complete 2026 Guide

    AI agent enterprise data security compliance is the set of controls that keep an autonomous AI agent from leaking data, taking unauthorized actions, or breaking regulations while it works inside your business. It is different from ordinary software security because an agent does not just read data, it acts: it has permissions, calls tools, and makes decisions.

    The essentials are least-privilege access, full audit logging of every action, human approval for high-risk steps, defense against prompt injection, and mapping the agent to the frameworks that apply to you (GDPR, SOC 2, ISO 27001, and the EU AI Act, whose high-risk rules take effect on 2 August 2026). Treat the agent as a powerful new employee with system access, and secure it like one.

    Getting AI agent enterprise data security compliance right is now the hard part of deploying agents, not building them. The models are capable enough. The blocker in most enterprises is proving that an autonomous system with access to customer data, internal tools, and the ability to act will not leak, break a rule, or do something no one authorized. That is a fair concern, and it has real answers.

    This guide is the practical version for teams actually deploying agents. It covers why agent security is different, what compliance actually involves, the specific risks that matter in 2026, how to handle permissions and audit trails, which regulations apply, how to evaluate a vendor, and a concrete checklist to secure an enterprise agent. We build production AI agents at Mobilions, and security and compliance are where most of the engineering effort goes, so this is a practitioner’s view rather than a policy summary.


    Why AI agent security is different from normal software security

    The instinct is to treat an AI agent like any other software vendor or SaaS tool. That instinct undersells the problem, and the difference is the whole reason this is hard.

    Ordinary software follows fixed rules. It does exactly what it was coded to do, and you secure it by controlling its inputs and its access. An AI agent is different in three ways. It acts, calling tools, sending messages, changing records, not just returning information. It has agency, choosing what to do next based on a goal rather than a script, which means its exact behaviour is not fully predictable in advance. And it is manipulable through language, because the same natural-language interface that makes it useful can be hijacked by carefully crafted text.

    Put those together and an agent is less like a database and more like a new employee who is fast, tireless, literal, and occasionally gullible, and who has been handed system access on day one. You would not give a new hire unlimited access to everything and no oversight. The same logic, applied rigorously, is what agent security is.

    AI agent enterprise data security compliance: what it actually covers

    It helps to define the scope plainly, because the phrase covers several distinct jobs. Strong AI agent enterprise data security compliance rests on a few pillars, and a gap in any one is where incidents come from.

    The six pillars of AI agent enterprise data security compliance: access, action, audit, data, threat, regulatory

    Access control: exactly what data and tools the agent can reach, kept to the minimum it needs. Action control: which operations it can perform on its own, and which require a human to approve. Auditability: a complete, tamper-resistant log of everything the agent did, so you can review, investigate, and prove what happened. Data protection: encryption, control over whether your data trains anyone’s model, and clean deletion when you stop. Threat defence: protection against prompt injection and manipulation. And regulatory alignment: mapping all of the above to the laws and standards that apply to your business.

    Miss access control and the agent can reach too much. Miss auditability and you cannot prove compliance or investigate an incident. Miss threat defence and an attacker turns the agent’s power against you. AI agent enterprise data security compliance is getting all six right together, not picking the easy ones.

    The core risks in 2026

    The threats are not hypothetical any more, so it is worth being specific about what actually goes wrong.

    Prompt injection. This is the big one. An attacker hides instructions in content the agent reads, an email, a web page, a document, and the agent follows them, exfiltrating data or taking actions it should not. OWASP ranks prompt injection as the number one risk for LLM applications, and its 2026 reporting notes there is no complete fix even with frontier models, which is why defence in depth is the only credible strategy. Real, high-severity vulnerabilities in mainstream AI coding and assistant tools through 2025 and 2026 show this is being exploited in production, not just in labs.

    Excessive agency and over-permissioning. An agent given more access or autonomy than it needs is a large blast radius waiting for a trigger. The danger is simple: excessive agency is only a threat if someone can hijack it, and prompt injection is exactly how they do. The fix is least privilege, giving the agent the narrowest access and the fewest autonomous powers that still let it do its job.

    Data leakage. An agent with broad read access can surface sensitive data to the wrong user, include it in an output, or send it somewhere it should not go, often without any malicious attacker involved, just a poorly scoped permission.Enforcing this consistently is the job of a fabric architecture for AI systems, which centralizes access and audit across every model and agent

    Unauthorized actions. Because agents act, an error or a manipulation can turn into a real-world consequence: a wrong record changed, a message sent, a payment attempted. This is why high-risk actions need a human in the loop.

    Unwanted training on your data. If your data flows to a vendor’s model and is used for training, it can effectively leak into a system you do not control. Knowing, and contractually controlling, whether your data trains anyone’s model is a core compliance question.

    Weak oversight. The quiet risk is simply not watching. One 2026 industry survey found only a minority of organizations monitor their AI activity end to end, which means most would not notice a problem until after it caused damage.

    Permissions and access control: the foundation

    If you fix only one thing, fix this, because most agent incidents trace back to an agent that could reach or do too much.

    The governing principle is least privilege: the agent gets the minimum data access and the fewest tool permissions it needs for its specific job, and nothing more. A support agent that answers order questions needs read access to orders, not write access to the finance system. Access should be role-based and scoped, ideally with the agent holding its own identity and permissions rather than borrowing a human’s or a shared admin account, so its actions are attributable and its access is independently controllable.

    A common and important question: should an Agentic ai development have the same access as the employee who runs it? The answer is no. An agent operates faster, at scale, and can be manipulated in ways a person cannot, so it should usually have narrower access than a human doing the same role, with the riskiest capabilities removed entirely or gated behind human approval. Give it employee-level access to everything and you have created an employee who never sleeps, can be tricked with a paragraph of text, and touches your whole system.

    Audit trails and monitoring

    You cannot secure or prove compliance for something you cannot see, so logging is not optional.

    Every meaningful action an agent takes, what it accessed, what it decided, what it did, should be recorded in a complete, time-stamped, tamper-resistant log. Good audit trails do three jobs: they let you investigate when something looks wrong, they let you prove to auditors and regulators what the agent did and did not do, and they let you improve the system by seeing how it actually behaves. Pair the logs with active monitoring and alerting, so unusual behaviour, a spike in data access, an unexpected action, surfaces in near real time rather than in a post-incident review.

    How often should you review? Continuously through automated monitoring, with scheduled human reviews for high-stakes agents. The regulatory direction is the same: the EU AI Act’s high-risk rules require automatic logging and human oversight, so building this in now is also future-proofing.

    Which regulations actually apply

    Compliance is not one rule; it is a stack, and which parts apply depends on your data and industry. The main pieces in 2026:

    AI agent compliance stack 2026: GDPR, SOC 2, ISO 27001, NIST AI RMF, and the EU AI Act deadline

    GDPR governs personal data of EU residents, including a hard rule on international transfers (Chapter V) that is triggered every time data crosses a border, which is easy to do accidentally through an AI API. SOC 2 (AICPA) is the external evidence most enterprise buyers ask a vendor for, covering security, availability, and confidentiality controls. ISO 27001 and the AI-specific ISO/IEC 42001 are the international management-system standards. the NIST AI Risk Management Framework is the voluntary framework most enterprises use internally to organize their AI program.

    And the EU AI Act is the big regulatory shift: its obligations for high-risk AI, including incident reporting, log retention, human oversight, and impact assessments, become legally binding on 2 August 2026, as the regulation sets out. In practice, agent governance leans on SOC 2, GDPR, and ISO 27001 for evidence, while NIST AI RMF and the EU AI Act shape the internal program. You do not need all of them; you need the ones that match your customers, data, and jurisdictions, mapped deliberately.

    How to evaluate an AI agent vendor

    If you are buying rather than building, the vendor’s security is your security, so evaluate it properly rather than trusting a marketing page.

    Ask for concrete evidence, not assurances. A current SOC 2 Type II report and ISO 27001 certification are table stakes for enterprise use. Ask directly whether your data is used to train their models (the answer should be no, in writing), where your data is stored and processed (for data-residency compliance), what audit logs you get access to, and how they defend against prompt injection. Push on the security agreement: it should cover data ownership, breach notification, deletion on offboarding, and liability. Watch for red flags, vague answers about data use, no independent certifications, no audit access, or an unwillingness to put commitments in the contract.

    Is SOC 2 alone enough? It is necessary but not sufficient. SOC 2 tells you the vendor has security controls; it does not tell you the agent is scoped to least privilege in your environment, or how it handles your specific regulatory obligations. Treat SOC 2 as a floor, not a finish line. ai automation services.

    Build vs buy, from a security angle

    The build-or-buy decision looks different through a security lens, and it is worth weighing deliberately.

    Buying a mature agent platform means inheriting a vendor’s security investment, certifications, and patch cadence, which is real value, at the cost of trusting their controls, their data handling, and their prompt-injection defences, and accepting the residency and training-data terms they offer. Building (or having a partner build) a custom agent means the data stays in your environment and under your controls, permissions and logging are exactly what you specify, and there is no third-party training-data question, at the cost of owning the security engineering yourself.

    For agents that touch highly sensitive or heavily regulated data, the control of a custom build often wins; for lower-risk, standard workflows, a well-certified vendor is usually the faster, sensible path. Either way, the security requirements are the same, only who implements them changes.

    Data lifecycle: encryption, training, and offboarding

    Security does not end at access; it follows the data through its whole life with the agent.

    Encrypt sensitive data in transit and at rest, and consider what the agent actually needs to see, sometimes it can work on masked or tokenized data rather than the raw records. Control training use contractually and technically, so your data is not absorbed into a model you do not govern. And plan offboarding before you need it: when you stop using an agent or vendor, you should be able to confirm your data is deleted, exports are handled, and access is revoked, cleanly and verifiably. The question “what happens to my data if I stop using this agent” should have a clear answer before you start, not after.

    Incident response and liability

    Even well-secured systems fail sometimes, so plan for it, because improvising during an incident is how a contained problem becomes a reportable breach.

    Have an incident-response plan that treats the agent as a first-class system: how you detect a problem, how you contain it (including the ability to quickly restrict or shut down the agent’s access), how you investigate using the audit trail, and how you meet notification obligations. Liability is a genuinely unsettled area, when an agent takes a harmful unauthorized action, responsibility can sit with the deploying company, the vendor, or both, depending on the contract and the regulation, which is exactly why the security agreement and the human-approval gates matter.

    Some enterprises are now looking at insurance for AI-related risk, though coverage is still maturing. The practical protection is the same as the prevention: least privilege, human approval on high-risk actions, and complete logs.

    A practical checklist to secure an enterprise AI agent

    Pulling it together, here is the short version of AI agent enterprise data security compliance you can actually work from.

    Scope the agent to least-privilege data and tool access. Give it its own identity, not a shared or human account. Require human approval for high-risk or irreversible actions. Log every action to a complete, tamper-resistant audit trail, and monitor it actively. Defend against prompt injection with input and output filtering and defence in depth, and test adversarially.

    Encrypt sensitive data and control whether it trains any model. Map the agent to your applicable frameworks (GDPR, SOC 2, ISO 27001, NIST AI RMF, EU AI Act) and keep the evidence. Vet vendors for certifications, data-use terms, residency, and audit access. And plan incident response and clean offboarding before launch, not after. Do these, and you have covered the ground that almost every incident comes from.

    How Mobilions helps

    We build production AI agents for enterprises, and security and compliance are the core of how we build, not an afterthought bolted on at the end. We scope agents to least privilege by default, give each agent its own identity and complete audit logging, gate high-risk actions behind human approval, and design in defences against prompt injection rather than assuming the model will protect itself.

    We keep your data in your environment where the sensitivity calls for it, control training use, and map the build to the frameworks you answer to, GDPR, SOC 2, ISO 27001, NIST AI RMF, and the EU AI Act, so the agent is defensible to your security team and your auditors. You own the code, the data, and the logs.

    What we will not do is ship an over-permissioned agent with no audit trail to hit a deadline, because that is precisely the agent that becomes an incident.

    The bottom line

    AI agent enterprise data security compliance is now the deciding factor in whether an agent reaches production, and it is a solvable engineering problem, not a reason to avoid agents. The mindset that works is to treat the agent as a powerful new employee with system access: give it the least access it needs, require approval for the risky moves, log everything, defend the language interface it runs on, and map it to the rules that apply to you.

    The threats are real, prompt injection has no complete fix, over-permissioned agents have a large blast radius, and regulation is tightening with the EU AI Act’s high-risk rules landing in August 2026. But every one of them has a known control, and together they are a checklist, not a mystery. Get the controls right and you can deploy agents that are genuinely useful and genuinely safe. Skip them and you are one crafted paragraph away from an incident.

    If you want a straight assessment of how to secure a specific agent for your data and your regulators, that is exactly the conversation our senior engineers have with enterprise teams every week.

    Book a discovery call for an honest review, no obligation. You can also explore our AI agent development services and how we approach applied AI.

    Key takeaways

    • AI agent security is different from ordinary software security because agents act, choose, and can be manipulated through language; treat an agent as a powerful new employee with system access.
    • AI agent enterprise data security compliance rests on six pillars: access control, action control, auditability, data protection, threat defence, and regulatory alignment.
    • Prompt injection is the top risk (OWASP LLM01) and has no complete fix, so defence in depth is the only credible strategy.
    • Least privilege is the foundation: give the agent the narrowest data and tool access, its own identity, and human approval for high-risk actions. It should have less access than the employee who runs it.
    • Log every action to a complete, tamper-resistant audit trail and monitor it actively; most organizations still do not monitor AI end to end.
    • Map the agent to the frameworks that apply, GDPR, SOC 2, ISO 27001, NIST AI RMF, and the EU AI Act, whose high-risk rules take effect 2 August 2026.
    • Vet vendors for SOC 2, data-use and residency terms, and audit access; SOC 2 is a floor, not a finish line. Plan encryption, training-data control, incident response, and clean offboarding before launch.

    Frequently asked questions

    What is AI agent enterprise data security compliance?

    It is the set of controls that keep an autonomous AI agent from leaking data, taking unauthorized actions, or breaking regulations while it operates inside a business. It spans least-privilege access, human approval for risky actions, complete audit logging, defence against prompt injection, data protection, and mapping the agent to applicable laws and standards like GDPR, SOC 2, and the EU AI Act. In short, it is securing and governing an agent that can act, not just read.

    Why is securing an AI agent harder than securing normal software?

    Because an agent acts rather than just returning information, chooses its next step based on a goal rather than a fixed script, and can be manipulated through the same natural-language interface that makes it useful. That combination means its behaviour is not fully predictable and its access can be turned against you, so it needs the kind of oversight you would give a new employee with system access, not the kind you give a static tool.

    What is prompt injection and why does it matter so much?

    Prompt injection is when an attacker hides instructions in content the agent reads, an email, a document, a web page, and the agent follows them, leaking data or taking unauthorized actions. OWASP ranks it the number one risk for LLM applications, and there is no complete fix even with the best current models. It matters because it is the main way an attacker hijacks an agent’s permissions, which is why least privilege and human approval on risky actions are essential.

    Should my AI agent have the same access as my employees?

    No. An agent works faster, at scale, and can be manipulated in ways a person cannot, so it should usually have narrower access than a human in the same role, with the riskiest capabilities removed or gated behind human approval. Giving an agent full employee-level access creates a system that never sleeps, can be tricked with text, and touches everything, which is a large and unnecessary blast radius.

    How do I prevent an AI agent from leaking company data?

    Scope its data access to the minimum it needs (least privilege), give it its own identity so access is controllable and attributable, filter its inputs and outputs, encrypt sensitive data, control whether your data trains any model, and log every action so you can detect and investigate leaks. Most leakage comes from over-broad permissions rather than sophisticated attacks, so tight scoping is the highest-value control.

    Which regulations apply to enterprise AI agents?

    It depends on your data and industry, but the common stack is GDPR (EU personal data, including cross-border transfer rules), SOC 2 (the security evidence buyers ask for), ISO 27001 and ISO/IEC 42001 (management-system standards), NIST AI RMF (internal program framework), and the EU AI Act, whose high-risk obligations become binding on 2 August 2026. Map the ones that match your customers, data, and jurisdictions rather than trying to satisfy all of them.

    Is SOC 2 compliance enough for an AI agent vendor?

    It is necessary but not sufficient. SOC 2 shows a vendor has security controls, but it does not tell you the agent is scoped to least privilege in your environment, whether your data trains their model, where it is stored, or how they defend against prompt injection. Treat SOC 2 as a floor and ask specifically about data use, residency, audit access, and injection defence on top of it.

    How do I audit what my AI agent is doing?

    Log every meaningful action, what it accessed, decided, and did, to a complete, time-stamped, tamper-resistant trail, and pair it with active monitoring that alerts on unusual behaviour. Review continuously through automated monitoring and schedule human reviews for high-stakes agents. Good logs let you investigate incidents, prove compliance to auditors, and improve the system, and the EU AI Act will require this kind of logging for high-risk AI anyway.

    Should I build or buy an AI agent for security reasons?

    Buying gives you a vendor’s security investment and certifications but means trusting their controls, data handling, and terms. Building or having a partner build keeps data in your environment with permissions and logging exactly as you specify and no third-party training question, at the cost of owning the security work. For highly sensitive or regulated data, the control of a custom build often wins; for standard, lower-risk workflows, a well-certified vendor is usually the faster path.

    What happens to my data if I stop using an AI agent?

    That should be settled before you start. A proper agreement specifies that on offboarding your data is deleted, exports are provided, and access is revoked, verifiably. If a vendor cannot clearly explain deletion and offboarding, treat it as a red flag, because unclear data handling at the end often signals unclear handling throughout.

    Does Mobilions build secure, compliant AI agents?

    Yes. We build production agents with least-privilege access, per-agent identity, complete audit logging, human approval on high-risk actions, and designed-in defences against prompt injection, mapped to the frameworks you answer to, GDPR, SOC 2, ISO 27001, NIST AI RMF, and the EU AI Act. You own the code, data, and logs. Book a discovery call for a straight assessment of how to secure an agent for your data and regulators.

  • Latest AI Agent Frameworks in 2026: What Changed and Which to Choose

    Latest AI Agent Frameworks in 2026: What Changed and Which to Choose

    Among the latest AI agent frameworks 2026, there is no single best one, there is a best one for your situation. LangGraph leads for production, stateful agents; CrewAI is fastest for role-based multi-agent prototypes; the new Microsoft Agent Framework is the unified successor to AutoGen for Microsoft stacks; OpenAI’s Agents SDK is simplest if you are all-in on OpenAI; and Google’s ADK suits Gemini-first teams. The bigger shift is underneath the frameworks: the MCP standard now connects agents to tools everywhere, and no-code platforms like n8n let non-developers build real agents. Pick the framework that matches your stack, your team’s skill, and whether you need production reliability or a quick prototype.

    The latest AI agent frameworks 2026 landscape brought bigger shifts than any single new feature, and it now moves fast enough that a guide written six months ago is already wrong in places. Frameworks that were the obvious choice last year are in maintenance mode now, new standards have quietly become universal, and a wave of no-code tools has made “which framework” a question even non-developers have to answer.

    This guide cuts through it. It covers what actually changed in 2026, the frameworks that matter and what each is genuinely best at, the protocols that now sit underneath all of them, the no-code route for non-technical teams, and a straight decision guide for choosing. We build production agents at Mobilions across these frameworks, so this is a practitioner’s view, not a leaderboard. Where a framework is overhyped or fading, this guide says so. A framework runs the agent, but the data, retrieval, and governance around it belong to a broader AI fabric architecture.

    Latest AI Agent Frameworks 2026: What Actually Changed

    A few shifts define the latest AI agent frameworks 2026, and they matter more than any single framework’s new features.

    AutoGen faded, Microsoft consolidated. AutoGen, one of the early multi-agent favorites, is now in maintenance mode: no new features, community-managed. Microsoft folded its agent work into a single Microsoft Agent Framework, the unified successor to AutoGen and Semantic Kernel, with graph-based workflows, responsible-AI guardrails through Azure AI Foundry, and both Python and .NET runtimes. If you were on AutoGen, this is where the road now leads.

    MCP became the universal standard. The Model Context Protocol (MCP), which standardizes how an agent connects to tools and data, went from a promising idea to something every major lab and IDE ships: Claude, OpenAI, Google’s Gemini and Vertex AI, Cursor, Windsurf, JetBrains, and more. This is the biggest quiet change of the year, because it means tool integration is no longer framework-specific glue, it is a shared standard.

    Protocols split into two jobs. Alongside MCP (agent to tools), the A2A protocol emerged for agent-to-agent coordination. The clean way to remember it: MCP gives your agent hands, A2A gives your agents colleagues.

    No-code got real. Platforms like n8n, with over a thousand integration nodes and now MCP support, made it genuinely possible for non-developers to build working agents, not toys. The “do I even need a framework” question is now a legitimate one for many teams.

    With that context, here are the frameworks themselves.

    The main AI agent frameworks in 2026

    There is no universal winner among the latest AI agent frameworks 2026, because each optimizes for something different. Here is what each is genuinely best at.

    LangGraph (LangChain)

    LangGraph is the most battle-tested choice for production, stateful agents that need tight control. It models an agent as a directed graph with conditional edges, which gives you precise control over flow, plus built-in checkpointing with time-travel debugging, so you can inspect and rewind an agent’s state. It is model-agnostic, pairs with LangSmith for enterprise-grade observability and evaluation, and now has Deep Agents for long-running workflows. The trade-off is a steeper learning curve. If you are shipping a serious agent to production, this is usually the default.

    CrewAI

    CrewAI has the lowest barrier to entry. It uses a role-based mental model (you define agents as roles working in a crew), and you can be running in about twenty lines. It is model-agnostic and ideal for getting a team-based, multi-agent prototype working quickly. It is the framework to reach for when you want to prove an idea fast, and many teams keep it for production too once it fits.Choosing and wiring these frameworks is the core of our agentic AI development work.

    Microsoft Agent Framework

    The new unified framework for the Microsoft stack, replacing AutoGen and Semantic Kernel. It offers graph-based workflows, responsible-AI guardrails via Azure AI Foundry, and both Python and .NET runtimes at 1.0 general availability. If your organization already runs on Azure and Microsoft tooling, this is the natural home.

    OpenAI Agents SDK

    The simplest path if you are committed to OpenAI models. It uses explicit handoffs between agents and context variables for state (ephemeral by default). The limitation is the flip side of its simplicity: it is restricted to OpenAI models, so it is a poor fit if you want model flexibility.

    Google ADK

    Google’s Agent Development Kit organizes agents into a hierarchical tree and is optimized for Gemini, though it supports other models. It is the sensible choice for Gemini-first and Google Cloud teams.

    Mastra

    Mastra is TypeScript-native, which makes it the natural fit for JavaScript and TypeScript teams building AI into web applications rather than working in Python. It handles persistent memory and long-running operations, so it is a real production option, not just a convenience.

    Framework comparison at a glance

    AI agent frameworks 2026 compared: LangGraph, CrewAI, Microsoft Agent Framework, OpenAI Agents SDK, Google ADK, Mastra and what each is best for
    FrameworkBest forModel supportLearning curve
    LangGraphProduction, stateful, controlAnyHigher
    CrewAIFast role-based prototypesAnyLow
    Microsoft Agent FrameworkMicrosoft / Azure stacksAny (Azure-centric)Medium
    OpenAI Agents SDKOpenAI-only, simple buildsOpenAI onlyLow
    Google ADKGemini / Google CloudGemini-first, othersMedium
    MastraTypeScript / web appsAnyMedium

    The honest summary: LangGraph for production control, CrewAI for speed, Microsoft or Google or OpenAI if you are committed to their ecosystem, and Mastra if you live in TypeScript.

    The protocols that now sit underneath everything

    In 2026 the frameworks matter less than they used to, because two standards do a lot of the heavy lifting no matter which framework you pick.

    MCP vs A2A: MCP connects an agent to tools, A2A connects agents to each other

    MCP (Model Context Protocol) standardizes how a single agent connects to tools and data. It is the USB-C port for AI: one interface that lets any agent plug into any tool. Because every major lab and IDE now supports it, building integrations is increasingly a matter of using a standard rather than writing custom connectors. If you are starting today, MCP is the first thing to adopt.

    A2A (Agent-to-Agent Protocol) standardizes how multiple agents discover each other, delegate tasks, and pass work back and forth. It is the coordination layer for multi-agent systems. Most teams need MCP first and reach for A2A only when they genuinely have multiple agents that must collaborate.

    The practical takeaway: choose a framework, but build on MCP, because it keeps your tool integrations portable across frameworks and future changes.

    The no-code and low-code route

    Not every agent needs a framework and an engineering team. Low-code platforms like n8n are event-driven tools that expose HTTP, conditional routing, and AI nodes without custom agent code, and with over a thousand integration nodes plus MCP support, they can build genuinely useful agents. This substantially lowers the barrier for non-technical teams.

    The honest guidance: for standard, well-defined workflows, a no-code platform may be the right answer and can save you a large custom build. Reach for a code framework when your agent is unusual, needs deep custom logic, has to integrate in ways the platform cannot, or must run at a scale and reliability the no-code tool was not built for. Starting no-code to prove value, then moving to a framework if you outgrow it, is a perfectly sensible path.

    How to choose your framework

    Cut through the options with a few questions rather than chasing whichever framework is trending.

    Start with your ecosystem: if you are deep in Azure, Microsoft Agent Framework; all-in on OpenAI, the OpenAI Agents SDK; Gemini and Google Cloud, ADK. If you want model flexibility, LangGraph or CrewAI. Then your team’s skill and speed: CrewAI or a no-code platform for the fastest start, LangGraph when you need production control and can absorb the learning curve, Mastra if your team is TypeScript. Then production versus prototype: for anything that has to run reliably with state, monitoring, and long workflows, favor LangGraph, Mastra, or CrewAI with proper observability; for a quick proof, almost anything works. Finally, whether you even need to build: try no-code first for standard tasks.

    Whatever you pick, build on MCP so your tool integrations stay portable, and choose based on your problem, not on which framework got the most stars this quarter.

    How long it takes to get productive

    A fair question before you commit: how long until your team is actually building. With a no-code platform, a non-developer can have a working flow the same day. With CrewAI, a developer can get a role-based prototype running in an afternoon, because the mental model is simple and it takes about twenty lines to start. LangGraph asks for more up front, usually a week or two to get comfortable with graphs, state, and checkpointing, but it pays that back on complex production systems.

    The Microsoft, Google, and OpenAI SDKs sit in between and are fastest if you already work in that ecosystem. The point is to be honest about the learning curve when you choose: a framework your team can actually use beats a more powerful one they fight.

    What if my framework gets abandoned

    This is a real worry, and AutoGen going into maintenance mode this year shows it is not hypothetical. Two things reduce the risk. First, favor frameworks with large, active communities and clear backing (LangGraph, CrewAI, the big-lab frameworks), because they are the least likely to be dropped and the easiest to hire for. Second, and more importantly, build on standards like MCP and keep your business logic and prompts separate from framework-specific code.

    When most of your value lives in your data, your tools (behind MCP), and your prompts rather than in one framework’s syntax, migrating to another framework is a manageable job rather than a rewrite. Lock-in comes from tangling your logic into a framework, not from choosing one.

    Common mistakes when choosing a framework

    A few patterns trip teams up. Chasing the trendiest framework instead of the one that fits your stack and skill leads to fighting the tool. Reaching for a heavy multi-agent framework when a single simple agent, or even a no-code flow, would do adds complexity you pay for forever. Ignoring observability and evaluation until something breaks in production is a classic, because an agent you cannot monitor is one you cannot trust. And betting everything on one framework’s proprietary features, rather than standards like MCP, is how you end up locked in. The fix for all of these is the same: match the tool to the problem, keep your logic portable, and build in monitoring from the start.

    How Mobilions helps

    We build production AI agents across these frameworks, and we have shipped AI since 2016. For teams choosing, we do the honest version: we recommend the framework that fits your stack, skill, and reliability needs rather than the one that is trending, and sometimes that recommendation is a no-code platform and no framework at all. We build on MCP so your integrations stay portable, design in observability and evaluation from the start, and hand you full ownership of the code. When AutoGen went into maintenance mode, the teams who had kept their logic portable barely noticed, and that is how we build.

    What we will not do is push a heavier framework than your problem needs, because the whole point of this guide is that the right choice is the one that fits, not the most impressive one.

    The bottom line

    The latest AI agent frameworks 2026 have a clear shape once you stop looking for a single winner. LangGraph for production control, CrewAI for fast prototypes, Microsoft or Google or OpenAI if you live in their ecosystem, Mastra for TypeScript, and no-code for standard workflows. Underneath all of them, MCP has become the standard worth building on, and A2A waits for when you truly need agents to coordinate.

    The durable advice outlasts any framework: choose based on your stack, your team, and whether you need production reliability or speed; build on open standards so you are not locked in; keep your real value in your data, tools, and prompts rather than one framework’s syntax; and add monitoring from day one. Do that, and it barely matters which framework wins the next quarter, because your agent will keep running and you will be able to move if you need to.

    If you are choosing a framework for a real agent and want a straight recommendation for your stack and use case, that is exactly the conversation our senior engineers have with teams every week.

    Book a discovery call and get an honest assessment, no obligation. You can also explore our AI agent development services.
    Key takeaways

    • There is no single best AI agent framework in 2026, only the best fit for your stack, skill, and reliability needs.
    • LangGraph leads for production and control; CrewAI for fast role-based prototypes; Microsoft Agent Framework, OpenAI Agents SDK, and Google ADK for their ecosystems; Mastra for TypeScript.
    • AutoGen is now in maintenance mode; Microsoft Agent Framework is its successor.
    • MCP became the universal standard for connecting agents to tools; A2A handles agent-to-agent coordination. Build on MCP first.
    • No-code platforms like n8n can build real agents and may replace a custom build for standard workflows.
    • Reduce abandonment and lock-in risk by favoring well-backed frameworks and keeping your logic and tools portable behind standards.
    • Choose by matching the tool to the problem, keep logic portable, and build in observability from the start.

    Frequently asked questions

    What are the best AI agent frameworks in 2026?

    The leading options are LangGraph (production, stateful control), CrewAI (fast role-based prototypes), the Microsoft Agent Framework (Microsoft and Azure stacks), OpenAI Agents SDK (OpenAI-only, simple), Google ADK (Gemini and Google Cloud), and Mastra (TypeScript). There is no single winner; the best one depends on your stack, skill, and whether you need production reliability or speed.

    Which AI agent framework should I choose?

    Start with your ecosystem (Azure, OpenAI, or Google point to their frameworks; model flexibility points to LangGraph or CrewAI), then your team’s skill and speed (CrewAI or no-code for fast starts, LangGraph for production control, Mastra for TypeScript), then whether you need production reliability or a quick prototype. Whatever you pick, build on MCP so integrations stay portable.

    Is LangGraph or CrewAI better?

    Neither is universally better. LangGraph is the more battle-tested choice for production, stateful agents that need control, with checkpointing and strong observability, at the cost of a steeper learning curve. CrewAI has the lowest barrier to entry and is ideal for getting a role-based multi-agent prototype running quickly. Many teams prototype in CrewAI and move to LangGraph for demanding production systems.

    Is AutoGen still worth using in 2026?

    AutoGen is now in maintenance mode, meaning no new features and community management. For new projects, the Microsoft Agent Framework is its unified successor, combining AutoGen and Semantic Kernel with graph workflows and Azure AI Foundry guardrails. Existing AutoGen projects still work, but new builds should start on the successor or another active framework.

    What is MCP and why does it matter?

    MCP, the Model Context Protocol, is a standard that lets any AI agent connect to tools and data through one universal interface, often called the USB-C of AI. It matters because every major lab and IDE now supports it, so tool integration is a shared standard rather than framework-specific glue. Building on MCP keeps your integrations portable across frameworks.

    What is the difference between MCP and A2A?

    MCP connects a single agent to tools and data, giving your agent hands. A2A connects multiple agents to each other so they can discover, delegate, and coordinate, giving your agents colleagues. Most teams adopt MCP first and only need A2A when they genuinely run multiple agents that must collaborate.

    Can I build an AI agent without coding?

    Yes. Low-code platforms like n8n expose AI nodes, routing, and over a thousand integrations without custom agent code, and now support MCP, so non-developers can build genuinely useful agents. For standard workflows this may be all you need; reach for a code framework when the agent is unusual, needs deep custom logic, or must run at a scale the no-code tool was not built for.

    Which AI agent framework is best for beginners?

    CrewAI has the lowest learning curve among code frameworks, with a role-based model you can start with in about twenty lines. For non-developers, a no-code platform like n8n is often the easiest entry point. Both let you prove an idea quickly before committing to a heavier, production-grade framework.

    What happens if my AI agent framework gets abandoned?

    It is a real risk, as AutoGen going into maintenance mode showed. Reduce it by favoring frameworks with large, active communities and clear backing, and, more importantly, by building on standards like MCP and keeping your prompts and business logic separate from framework-specific code. When your value lives in your data, tools, and prompts, migrating frameworks is a manageable job rather than a rewrite.

    Are AI agent frameworks model-agnostic?

    Some are, some are not. LangGraph, CrewAI, and Mastra are model-agnostic, so you can switch model providers. The OpenAI Agents SDK is restricted to OpenAI models, and Google ADK is optimized for Gemini while supporting others. If model flexibility matters to you, favor a model-agnostic framework.

    Do I need a framework at all for a simple agent?

    Often no. For a single, standard workflow, a no-code platform or even a direct model integration can be simpler and cheaper than a full framework. Frameworks earn their weight when you need multi-step orchestration, persistent state, multiple agents, or production-grade reliability and monitoring. Match the tool to the problem rather than defaulting to a framework.

    Does Mobilions build agents on these frameworks?

    Yes. We build production AI agents across LangGraph, CrewAI, and the major frameworks, and we recommend the one that fits your stack and use case rather than the trendiest. We build on MCP so your integrations stay portable, design in observability from the start, and hand you full ownership of the code. Book a discovery call for a straight recommendation.